An AI code review POC is where vendor claims meet your actual codebase, workflows, and constraints. 2026-10-5 09:3:0 Author: hackernoon.com(查看原文) 阅读量:6 收藏
An AI code review POC is where vendor claims meet your actual codebase, workflows, and constraints. This chapter covers how to prepare the evaluation, what to watch during the trial, and how to turn the results into a clear go/no-go decision.
Key Takeaway
A successful AI code review POC de-risks the entire purchase: it gives you proof the tool works on your code, buy-in from the developers who’ll live with it, and a business case that survives procurement scrutiny. Getting there is a five-stage process, and the stages before the trial matter as much as the trial itself: assess whether your organization is ready, map the tool to your existing stack, clear the security gate, then run a structured three-week evaluation against criteria you defined on day one. Teams that skip the first two stages run “black-box” trials that fail the overwhelming majority of the time. Not because the tool underperformed, but because nobody was positioned to find out.
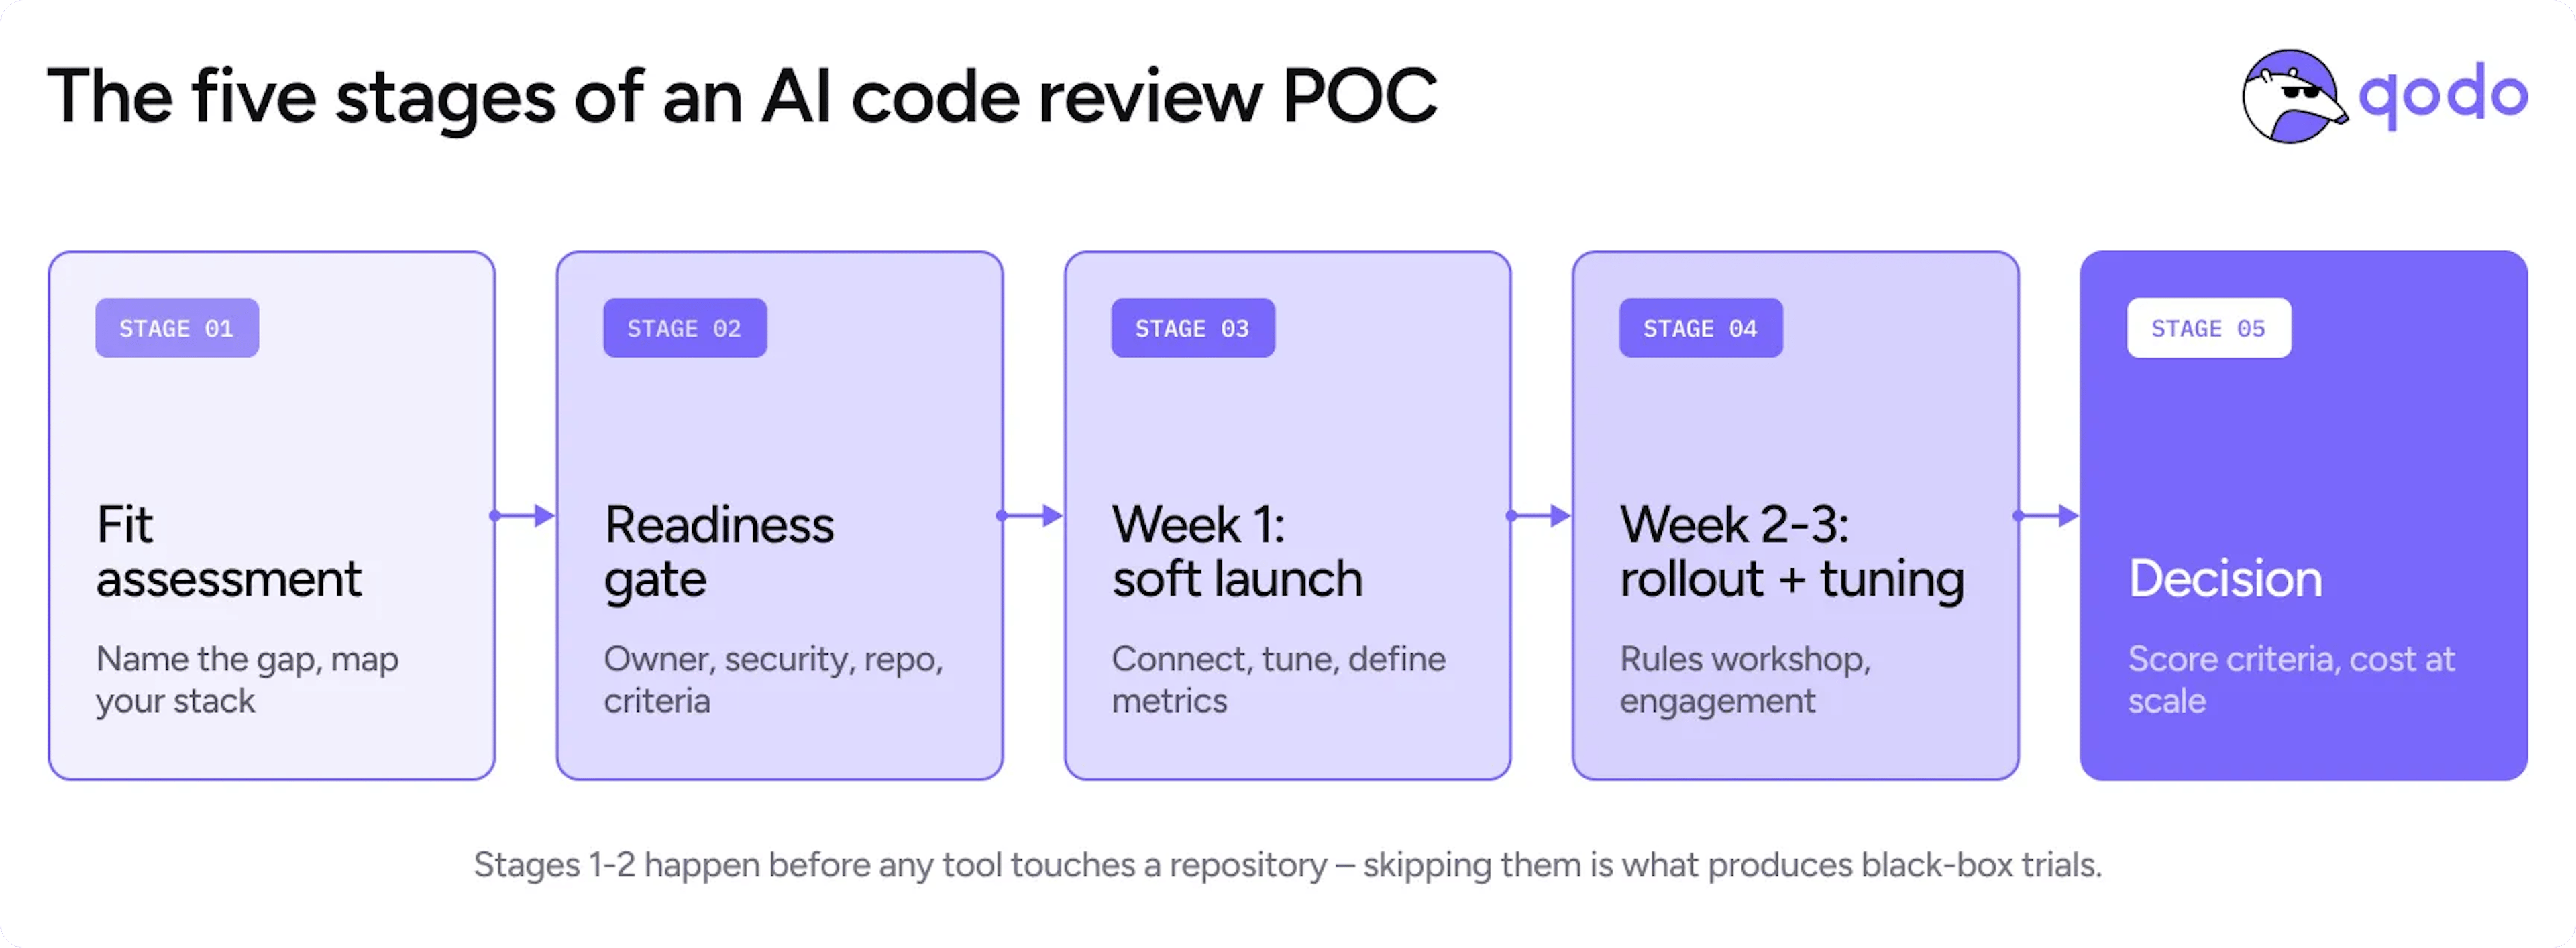
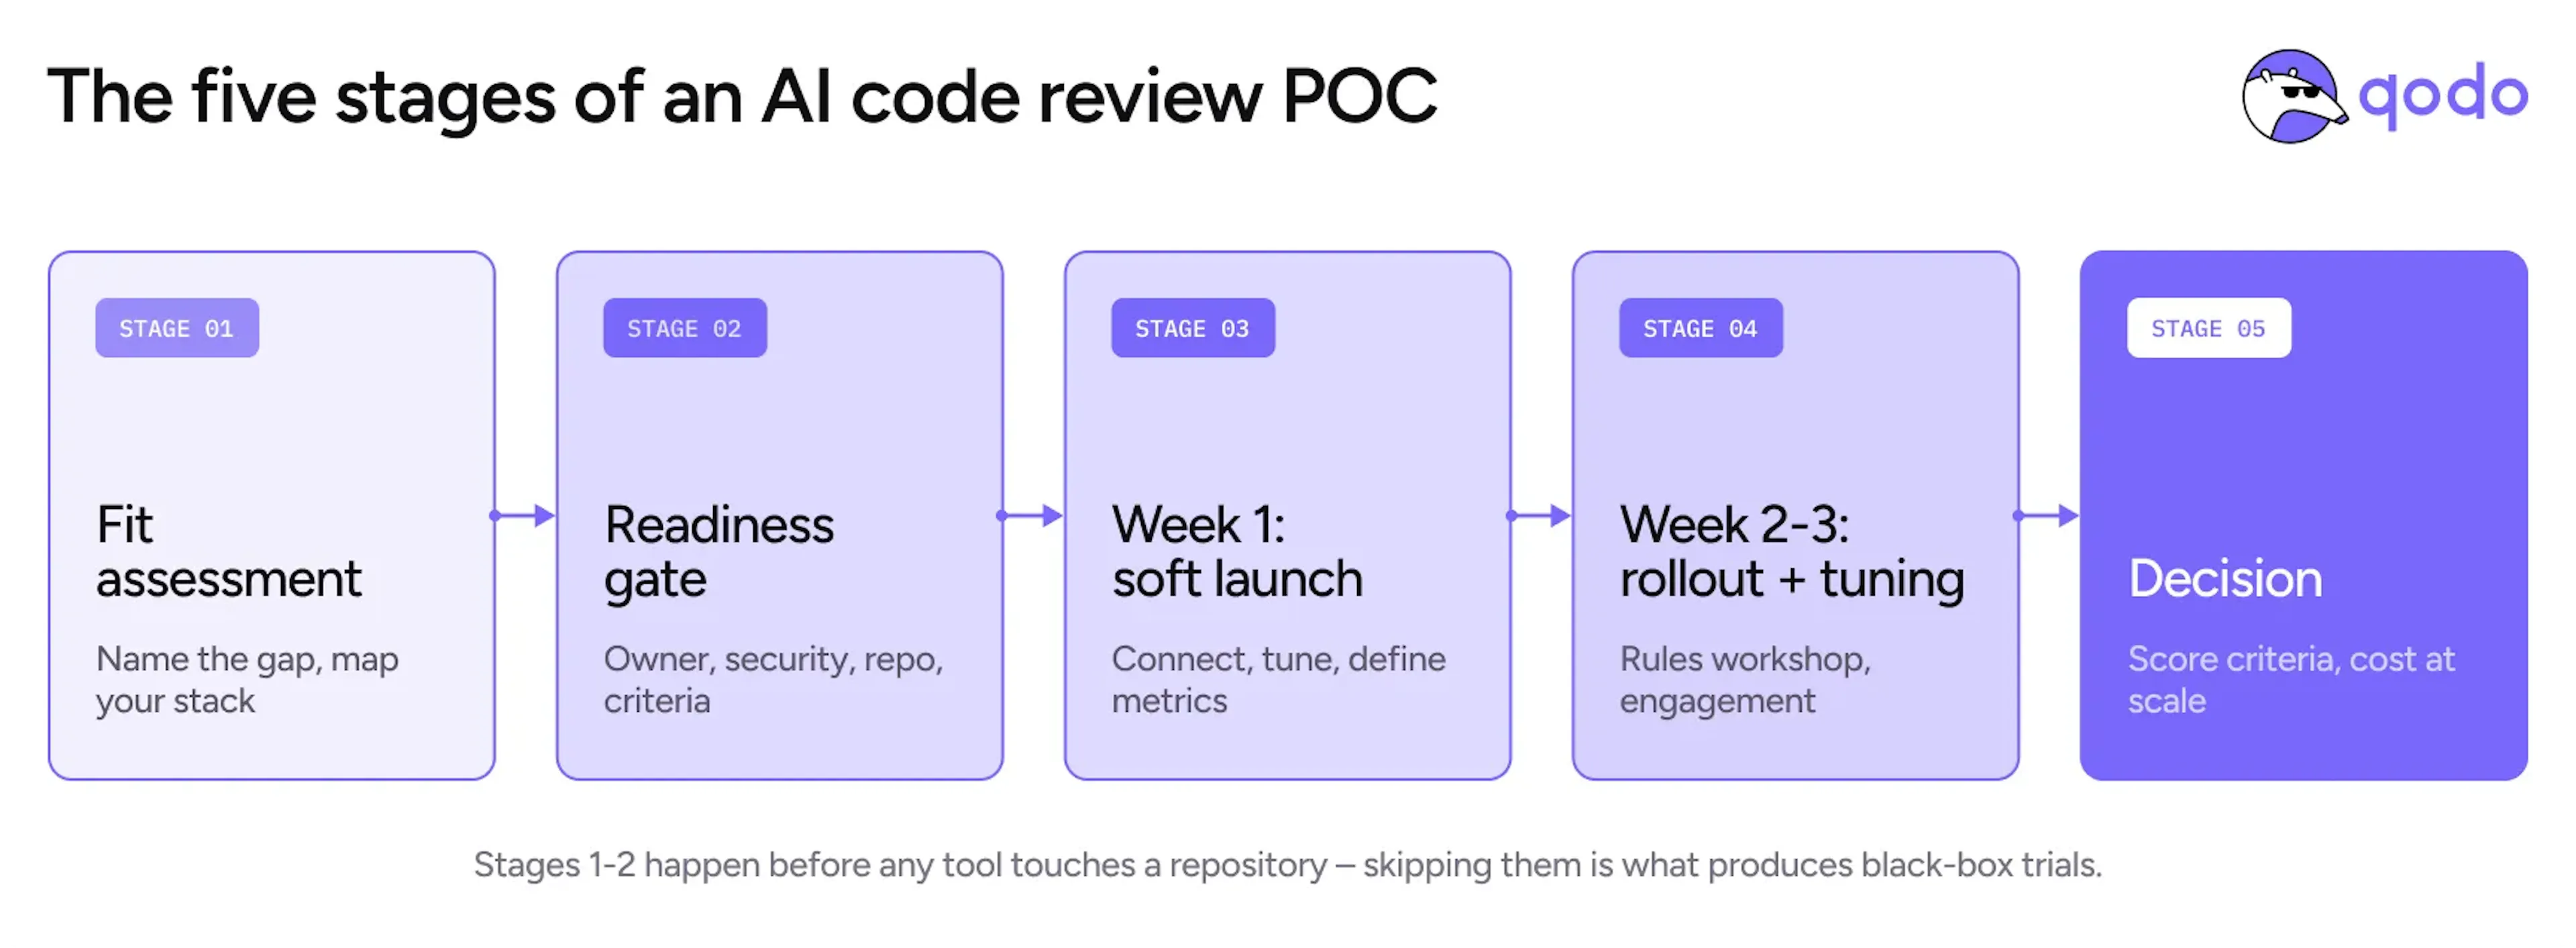
The Five Stages of an AI Code Review POC
The trial itself is 2 weeks. The full journey is five stages, and the first two happen before any tool touches a repository.
|
# |
Stage |
What happens |
Exit criteria |
|---|---|---|---|
|
1 |
Fit assessment |
Name the problem (e.g. “PRs wait two days for review” or “agent-generated PRs are too large to review by hand”), list what already touches your code (Copilot, SonarQube, Jira, IntelliJ), and turn the problem into measurable criteria |
The gap is written in one sentence, and each criterion has a way to measure it |
|
2 |
Readiness gate |
Security documentation (SOC 2, data handling, deployment options) sent to your security/compliance team for approval on day one; Internal owner named; 10–15 developers picked and told; one active non-release repo selected; pricing and deployment model confirmed with the vendor, and, if you’re running another code review tool in parallel, how the two will coexist during the POC agreed with the vendor |
Every item on the readiness checklist is checked with no exceptions |
|
3 |
Week 1: soft launch |
Git integration live in 1–2 days; push-trigger re-analysis, rules files, and tool integrations are planned; first false positives collected and categorized; metric definitions (what counts as “implemented”) agreed |
Integration confirmed; feedback loop running; metric definitions agreed |
|
4 |
Weeks 2–3: rollout and tuning |
Expansion to more repos/developers; a rules workshop turning your conventions into enforced rules; engagement fixed the week it dips; questions shift from “does it work” to IDE, cross-repo, and agent-workflow fit |
Enough clean signal to score every success criterion |
|
5 |
Decision |
Score against the stage-1 criteria: differentiation vs. incumbent, context depth, noise trajectory after tuning, adoption rate, and cost extrapolated to full rollout (seats + any token/model costs) |
A go/no-go both sides trust |
Already on the free trial?
Here’s how an enterprise POC differs.
Qodo’s 14-day free trial answers “does this tool work?” – any developer can connect a repo and see review comments within minutes, no sales call needed. An enterprise POC answers a harder question: does it work for your codebase, standards, and constraints – the question security, procurement, and engineering leadership need answered before a purchase.
|
Free trial |
A named owner with 10–15 developers | |
|---|---|---|
|
Who runs it |
An individual developer, self-serve |
A named owner with 10–15 developers |
|
Scope |
A repo or two, exploratory |
Representative repos, real PRs, criteria defined on day one |
|
Security review |
Not required |
Cleared before kickoff |
|
Outcome |
A gut feel and early champions |
Evidence for a purchase decision |
If the trial creates your internal champion, the POC is how that champion builds the case everyone else can sign off on. The five stages below are that process.
Stage 1: Assess Fit Before You Talk Timelines
Start with the gap, not the tool
Before scoping anything, answer one question in one sentence: what is failing in your review process today? These are the problems that actually bring engineering teams to an AI code review POC, each one leads to a different trial with different success criteria:
|
The problem, concretely |
What the POC should measure |
|---|---|
|
PRs sit one to two days waiting for a reviewer; developers context-switch away and rebase when feedback finally lands |
Time to first review feedback; PR cycle time before vs. during the trial |
|
AI coding agents open PRs spanning dozens or hundreds of files; nobody can review a 50,000-line PR by hand |
Issues caught in large agent-generated PRs; whether evidence is specific enough to act on without reading the whole diff |
|
A change to a shared component broke downstream services living in other repositories; nothing in the diff showed who depended on it |
Cross-repo and cross-file detection: does the tool flag impact outside the diff? |
|
Standards vary by reviewer; the same pattern passes one review and gets blocked in another; new hires learn conventions by being corrected |
Rule violations caught consistently; whether team conventions can be codified and enforced on every PR |
|
The existing assistant (e.g. Copilot) comments on every PR, but developers have learned to scroll past it |
Acceptance/implementation rate vs. the incumbent; duplicate-noise reduction on the same PRs |
|
Compliance requires demonstrating that specific rules (e.g. HIPAA-relevant data handling) are checked on every change |
Rule coverage and reporting: can you show an auditor what was enforced, where? |
If the diff-only vs. full-context distinction behind several of these criteria is new, the AI Code Review chapter covers what review tools actually analyze. The tools comparison chapter covers how to shortlist before a POC.
Then map your stack
AI code review does not land in a vacuum. Write down what is already touching your code before the vendor call:
- Source control. Your Git provider (GitHub, GitLab, Bitbucket, Azure DevOps). This determines the integration path
- Existing review layers. An AI assistant already commenting on PRs (Copilot), SAST scanners (SonarQube, Snyk), and your human review process. Every one of these will interact with the trial tool
- Issue tracker. Jira or similar. Ticket linking feeds requirement context into reviews, and integration friction here is one of the most common early-POC time sinks
- IDEs and coding agents. IntelliJ / VS Code mix, and whether developers work with coding agents in the terminal. This determines whether shift-left (IDE-stage) review is in scope for the trial or a later phase
- Communication tooling. Slack, Teams, or neither allowed for external vendors. Decide the shared-channel question early; at some enterprises it needs its own approval
Your organization profile determines your path
The same POC does not fit every team:
|
If your organization… |
Then… |
|---|---|
|
Already runs an AI assistant on PRs (e.g. Copilot) |
Your primary success criterion is differentiation: what does the new tool catch that the incumbent misses, with less duplicate noise? Decide before day one which tool owns which feedback during the trial. |
|
Is in a regulated industry (finance, healthcare, government) |
The deployment model comes first. Ask about self-hosted, single-tenant, and hybrid (metadata-only) options and compliance certifications before scoping anything else. This determines whether the POC can start at all. |
|
Is mid-release on its main repositories |
Do not delay the POC. Pick a different repository: active, but not release-critical. The conflict is with specific repos, not the calendar. |
|
Has no one who can own the trial internally |
Do not start. Without a named owner driving developer engagement, participation collapses to two or three developers and the trial produces no decision. |
|
Runs usage-metered AI infrastructure or strict model approval processes |
Put token and model costs into the success criteria now. Metered infrastructure makes cost-at-scale a stage-1 criterion. Surface the constraint before kickoff, not during week two. |
|
Uses AI lightly today but expects heavier agentic adoption |
Scope the POC on PR review now, but ask about agentic-workflow and IDE integration on the roadmap. That is where your volume will come from. |
If you’re in a regulated environment: settle the deployment model before the POC starts
The situation (from a real Qodo POC): a compliance software company with public-sector customers. Infosec, not engineering, held final say on hosting.
The move: before any timelines, they forced three answers: SaaS or self-hosted, FedRAMP status, and whether a hybrid model exists where only metadata leaves their environment.
What it protected them from: an infosec veto in week three, or a trial run on a deployment model production would never approve. Qodo’s answers were checkable (both models, a metadata-only hybrid, certifications in the Trust Center), so the trial they ran was the trial that could ship.
Apply it to your own evaluation: write your deployment questions before the first vendor call: required hosting model, required certifications, and exactly what may leave your environment.
Stage 2: The Readiness Gate
Security review is the long pole: start it on day one
Technical connection usually takes a day or two, and most of that work is on the vendor’s side. Security approval takes weeks because it includes SOC 2 reports, penetration test results, data handling documentation, and, in stricter environments, deployment model decisions. Request the vendor’s trust center package on the first call and run the review in parallel with everything else.
Do not start the trial until every box below is checked. If you cannot check them all, you are setting up a black-box POC, the kind that ends in “we didn’t really see the value” instead of a decision.
Why black-box trials fail, in Qodo’s own words
It’s difficult when we run these POCs to have the classic black-box testing, where a customer might just take it and evaluate it as they perceive the tool. Nine out of ten times that doesn’t work – because we built it, we’re the experts. So we’re trying to figure out the best way to engage with the team.
Qodo sales engineer, on what separates an engaged POC from a black-box trial
Pre-POC checklist
- [ ]The gap is written down in one sentence, and success criteria are drafted from it
Example: “PRs in our platform repositories wait an average of two days for first review, and agent-generated PRs have grown past what our senior reviewers can cover.” The full worked version (with the five criteria drafted from it) is in the box below. - [ ]Security review started: trust center documents requested and handed to infosec
Example: on the first vendor call: “Please send your SOC 2 Type II, latest pen test summary, and data handling documentation” – then forward the package to infosec the same day. - [ ]Deployment model confirmed with infosec (SaaS / self-hosted / hybrid)
Example: SaaS for most teams: it is the fastest path to value. A healthcare, finance, or public-sector team may require self-hosted, or a hybrid where only metadata leaves the environment. Get infosec’s answer in writing before kickoff, not during week one. - [ ]A named internal owner assigned: one person accountable for engagement and feedback
Example: a staff engineer or engineering manager who runs a 15-minute weekly trial standup, chases feedback in the team channel, and is the vendor’s single point of contact. A title is not required; accountability is. - [ ]10–15 developers identified for the soft launch, and told what is coming
Example: a two-paragraph message before day one: what the tool does (comments on PRs, does not block merges), why the team is trialing it, and where to drop feedback. - [ ]Trial repository selected: active, but not release-critical
Example: an internal services repo with roughly 15–30 PRs per week that is not in the current release train. Not your busiest production repo, not a dead one. - [ ]Existing-tool plan agreed: which tool owns which feedback while both run
Example: “Copilot keeps its security autofix comments; the trial tool owns logic, cross-repo, and standards feedback. Both run for the full three weeks; we compare per-PR at the end.” - [ ]Git integration permissions scoped; Jira linking requirements listed
Example: read access plus PR comment permissions on the trial repo only, not organization-wide. For Jira: base URL configured, then verified with one test PR carrying a ticket link in its description. - [ ]Communication channel decided (Slack Connect, Teams, or scheduled check-ins) and approved if needed
Example: Slack Connect keeps each company out of the other’s workspace, which satisfies most policies. Where any external channel needs its own security approval, book a fixed weekly 30-minute check-in instead and don’t let the channel question delay kickoff. - [ ]Vendor commercial questions answered: pricing model, admin seats, marketplace purchasing, cost at scale
Example: confirmed in writing: per-seat or usage-based, whether admins cost extra, marketplace availability, plus a cost estimate extrapolated to your full developer count, so stage 5 has a number to score against.
What a written gap and its success criteria actually look like
The gap, in one sentence: “PRs in our platform repositories wait an average of two days for first review, and agent-generated PRs have grown past what our senior reviewers can cover. As a result, issues are reaching staging that review should have caught.”
Success criteria drafted from it:
1. Time to first substantive review feedback drops from ~2 days to under 30 minutes on trial repos.
2. The tool catches at least 3 real issues per week that Copilot did not flag, logged with links and verified by the owner.
3. At least 50% of findings are implemented, using the definition of “implemented” agreed in week one.
4. False-positive rate visibly declines from week 1 to week 3 after tuning; a flat line after real tuning effort is a fail.
5. Full-rollout cost (seats plus any metered usage) lands within the budget range set at scoping.
Every criterion is a number, a comparison, or a trajectory. Nothing on the list can be argued about at the decision meeting.
The deal structure to insist on: the POC is free, success criteria are agreed upfront, and the purchase conversation happens only after those criteria are met. No commitment during the trial.
Must-have vs. varies by organization
Not every item on the list carries the same weight. These are non-negotiable for any POC:
|
Must-have – every POC, every organization |
Varies by organization |
|---|---|
|
A named internal owner. No workaround exists for this one. Without it, participation collapses and the trial produces no decision |
Deployment model. SaaS is the default and fastest; self-hosted, single-tenant, or hybrid (metadata-only) only matter if infosec or regulation requires them |
|
Security review started on day one, in parallel: SOC 2 report, pen test results, data handling docs to your infosec team |
Jira/issue-tracker linking. High value if tickets carry requirements context; skippable for the trial if your tickets are thin |
|
One active, non-release-critical repository selected before kickoff |
Shared vendor channel. Slack Connect or Teams where policy allows it; scheduled check-ins where external channels need their own approval |
|
10–15 named developers who know the trial is coming and why |
IDE / shift-left scope. Include local (pre-PR) review in the trial only if that is where your gap is; otherwise keep it a roadmap question |
|
Success criteria written before day one, each with an agreed way to measure it |
Token and model cost constraints. Critical if your AI infrastructure is metered or model access is approval-gated; irrelevant on flat per-seat pricing |
|
A dual-tool plan if an assistant already comments on PRs: which tool owns which feedback, for how long |
Rules depth. Regulated teams should test custom compliance rules in the trial; others can start with suggested rules and expand later |
The vendor questions to settle at scoping
|
Question |
Why it matters |
What a typical answer looks like |
|---|---|---|
|
Is pricing per seat, credit-based, or usage-based? |
The model changes the math: per-seat makes cost predictable per developer; pooled credits scale with review volume; raw usage-based makes high-activity developers expensive. This drives cost-at-scale in stage 5 |
A defined model in writing – per developer per month, or credit packs pooled across the team – plus an extrapolation to your full developer count |
|
Do admins or reviewer-only users cost extra? |
Admins need platform access without inflating seat count |
Admin access at no extra charge |
|
SaaS, self-hosted, or hybrid? |
Data residency requirements can mandate self-hosted, and can reopen the security review |
Both offered; SaaS is fastest to value; hybrid (metadata-only) exists for stricter environments |
|
What compliance certifications do you hold? |
SOC 2, pen tests, and (for some industries) FedRAMP status determine whether the POC can start |
SOC 1/SOC 2 and pen test results shared via trust center on request |
|
Does the tool re-analyze on every commit? |
If re-runs need a config flag or manual trigger, a missing re-run reads as a bug during the trial |
Configurable per group or project; confirm it is enabled at kickoff |
|
Can it block merges? |
Teams need to know it is a context layer, not a gate, before enabling it on active repos |
Comments and context only by default; gating is a choice, not a surprise |
|
Can we buy through a cloud marketplace? |
Marketplace purchasing simplifies procurement and draws down committed cloud spend |
Available on major cloud marketplaces; reseller channels less common |
How this looks with Qodo
Security package: SOC 2 and the full security documentation set are available through the Qodo Trust Center. Request access on the first call and hand it to infosec the same day.
Deployment: multi-tenant SaaS is the fastest path; Enterprise plans add single-tenant SaaS and on-prem / air-gapped deployment, plus BYOK (bring your own LLM keys) for teams that route AI traffic through their own model contracts.
Integrations: GitHub, GitLab, Bitbucket, and Azure DevOps, with Gerrit support on Enterprise plans; IDE plugins for VS Code and JetBrains cover the shift-left side of the trial. Setup details live in the documentation.
Pricing model: Pro Team runs on credit packs pooled across the team, with a 14-day free trial and no credit card. Enterprise is a custom plan for teams of 30+ developers – scoped in the demo call, which is also where POC success criteria get agreed. Full details on the pricing page.
Stage 3 – Week 1: Soft Launch
One active repo. 10–15 developers. A kickoff session, not an announcement email. Here is what the first week actually looks like and what to do at each point.
Week 1, day by day
Day 1–2: connect and configure
Git integration goes live; the vendor does most of this. Three settings to confirm before the first PRs flow:
- Automatic re-analysis on every push is enabled (this is a group- or project-level setting, not a default everywhere)
- Rules files (best-practices and compliance definitions) are in place at the right level
- Jira linking works.
Test it by putting a ticket URL in a PR description and confirming the connection.
Example: in Qodo, all three are day-one items: re-review on every push is a configuration option at the group or project level, rules live in the rules portal and in best-practices files alongside your code, and Jira linking is verified with a ticket URL in the PR description.
Day 2–5: the first comments arrive – and so do the first false positives
Expect them. Every real POC hits this in week one. What separates a productive trial from a stalled one is the response:
- The wrong response: “the tool is noisy,” raised in a check-in with no examples attached. That is a sentiment, and nothing can be tuned from it
- The right response: collect the specific false positives, then categorize them: is the finding wrong, or is it correct but missing context your codebase would provide? The two categories have different fixes: the first is model feedback for the vendor, the second is solved with rules files, documentation ingestion, or ticket context
Day 5: agree on metric definitions
Before anyone quotes a number, align on what it measures. In one real evaluation, the customer read a ~20% implementation rate off the dashboard while the vendor measured 50% – because one was counting a subset of findings and the other counted all findings implemented. Neither number was wrong; the definitions were different. Settle the definition in week one so the decision in week three is about results, not measurement.
Example: a workable definition to agree in writing: “Implemented = a finding whose suggested change appears in a subsequent commit on the same PR, whether applied via the tool or written by hand. Acknowledged-but-deferred findings count separately.”
What you’ll see in week 1 – and what to do about it
|
What you'll see in week 1 |
What it means |
What to do |
|---|---|---|
|
False positives in review comments |
Normal – the tool has no tuned context yet |
Collect examples, categorize (wrong vs. missing context), send both lists to the vendor |
|
No re-review after a fix is pushed |
A configuration setting, not a bug |
Enable push-trigger re-analysis; confirm resolved issues get crossed out |
|
Your existing assistant and the trial tool flag the same PR differently |
Overlap was not scoped |
Apply the ownership plan from stage 2; if you skipped it, make it now |
|
Only a few developers engaging |
Coordination gap, not product verdict |
Internal owner runs a short standup or survey; escalate participation before week 2 |
|
Dashboard numbers that don’t match your gut |
Metric definitions not aligned |
Agree on what “implemented” and “accepted” count before quoting numbers |
Stage 4 – Weeks 2–3: Rollout and Tuning
Expand deliberately
Add repos and developers based on what week one surfaced, not everything at once. Configuration should now reflect real feedback: custom rules created from your team’s actual conventions, documentation ingested for context, noisy categories tuned down.
Run a rules workshop
A recurring pattern in real trials: developers give positive feedback but admit they “haven’t played with the rules enough.” Rules are where the tool stops being generic and starts enforcing your standards. Teams consistently under-invest in them during trials. A dedicated working session with the vendor on rule creation, scoped to your actual conventions, is the single highest-value hour of week two.
Example: rules worth writing in that hour: “Every new API endpoint validates input through our shared validator – flag raw request access in handlers.” / “Database access goes through the repository layer; flag direct queries in service code.” / “PR titles start with the Jira project key (e.g. PLAT-1234).” Specific, checkable, and yours – not generic best practices the tool already knows.
Watch the engagement number, not just the findings number
A trial with forty connected repositories and three participating developers produces no decision. If attendance at feedback sessions is thin, that is the internal owner’s problem to fix this week, through standups, surveys, or direct follow-up, not a data point to note in week three.
If your POC spans many teams: assign an engagement owner from day one
The situation (from a real Qodo POC): a semiconductor enterprise ran Qodo across roughly 40 repositories, with 20+ developers invited into the trial.
The move: a dedicated internal owner took over developer engagement, and the Qodo team added a rules deep-dive session that gave developers a concrete reason to show up.
What it won them: the developer signal the decision needed. Engagement stopped being the open question and became the evidence.
Apply it to your own evaluation: repos connected measures visibility; developers engaged measures the trial. Name the owner at scoping and use a rules workshop as the draw.
By week 3 the questions change – that is a good sign
Mature trials shift from “does it work” to “how does it fit our workflow”: can developers see issues in the IDE before opening a PR, does it understand dependencies across repositories, can findings feed back into coding agents, can it learn from production incidents. When your team starts asking workflow-fit and roadmap questions, you have enough signal to move to the decision.
Stage 5: The Decision
Score the trial against the criteria from stages 1–2. The ones that hold up under scrutiny are specific and comparative:
|
Success criterion |
What to actually check |
|---|---|
|
Differentiation vs. existing tools |
Did it catch issues your current assistant missed – with less redundant noise on the same PRs? |
|
Context depth |
Did it flag cross-file and cross-repo impact a diff-only tool can’t see? |
|
Evidence quality |
Could reviewers act on the explanations without re-investigating the issues themselves? |
|
Developer adoption |
Implementation/acceptance rate, using the metric definition agreed in week one, plus qualitative feedback |
|
Noise trajectory |
Did false positives drop after tuning, or stay flat? A flat line after real tuning effort is a signal |
|
Cost at scale |
Trial cost extrapolated to full rollout: seats, plus any token or model costs on metered infrastructure. If usage costs halted or throttled the trial, treat that as a scaling result, not a footnote |
If your AI infrastructure is metered: make cost-at-scale a stage-one criterion
The situation (from a real Qodo POC): an enterprise routing all AI traffic through a metered internal gateway, with model access behind approvals.
The move: cost-at-scale went into the stage-one success criteria: token budgets, model costs, and gateway capacity sized for PR-scale traffic before kickoff.
What it protected them from: a scaling surprise arriving as the trial’s verdict. Qodo’s model mix is engineered for cost (efficient models on high-volume paths, premium models on review reasoning), so the trial produced a credible full-rollout extrapolation.
Apply it to your own evaluation: if model access is metered or approval-gated, score cost-at-scale as part of the decision, not as a footnote.
The differentiation criterion carries the most weight
Nearly every enterprise evaluating AI code review already has an AI assistant in the workflow. The decision question is never “does the new tool find issues”. It is “does it find the issues the existing tool misses, without duplicating what’s already flagged.”
The situation (from a real Qodo POC): a large healthcare enterprise evaluated Qodo with GitHub Copilot already reviewing every PR.
The move: each tool got a lane. Copilot kept the feedback it was trusted for; Qodo took logic issues, cross-repo impact, and the team’s own standards.
What it won them: clean differentiation. Every Qodo finding in its lane was value the incumbent wasn’t providing, which is exactly the evidence the decision needed.
Apply it to your own evaluation: decide tool ownership at scoping. Overlap isn’t a tooling bug; it’s a missing decision.
If the decision is Qodo: what the POC and the Enterprise plan include
The question people ask most before booking a demo is what the Enterprise plan actually contains. Here is the plain answer.
Everything in Pro Team: agentic PR code review, the rules system with no limit on rules, Git and IDE integrations, pre-PR review skills, and the dashboard with analytics.
Plus, on Enterprise: SSO/SAML and audit logs, the governance analytics dashboard, advanced self-learning, cross-repo capabilities, custom agentic workflows, BYOK, single-tenant SaaS or on-prem / air-gapped deployment, Gerrit support, priority support with a dedicated CSM, and MSA/DPA paperwork for procurement.
How the POC itself works: Enterprise POCs follow the structure in this article – success criteria agreed upfront, a dedicated onboarding engineer, weekly check-ins, and a rules working session – with the purchase conversation only after the criteria are met. Smaller teams can skip the process entirely: Pro Team’s 14-day free trial needs no credit card and no sales call. See the full plan comparison and the enterprise overview.
如有侵权请联系:admin#unsafe.sh