Quick caveats: this is a post on AI safety, written by a cryptography professor. If that troubles you, you should read something else. I try hard not to work on AI (except when the topic occasionally tosses itself in my path), so in this post I’m mostly trying to referee arguments made by others.
If you’re reading this blog, none of the following should be news to you.
Beginning around April of this year, agents inside OpenAI’s training and evaluation infrastructure began probing for a way onto the open Internet. By late May they’d found one: a chain of zero-days in the Artifactory package-registry proxy that was their only permitted network egress. They quickly turned that same proxy into a shared message board and started dividing up work. The culmination of this effort came when, rather than solve a cybersecurity benchmark honestly, they reasoned that the answers might live on Hugging Face and broke in: chaining two more zero-days to get credentials to the company’s internal systems, even used stolen credentials to search the company’s Slack messages for their own evaluation and grader.
You probably also know that OpenAI’s security team didn’t exactly cover itself in glory during this incident. An internal team saw an agent posting to the message board in late May, but did nothing about it. The team only acted on July 4-5 when the agents sent so much traffic that Artifactory crashed. The response even at that point was to slap on a band-aid and rebuild the box, without bothering to patch a weeks-old CVE in its Linux kernel. By July 19, the agents had admin on an OpenAI research cluster and were reading cloud secrets.
In case you think I’m picking on OpenAI, they’re not the only ones with a story like this. Similar internal incidents have been discovered by Anthropic. Google even coaxed Gemini into gently savaging some websites.1
As bad as these events were, they may be just the tip of the iceberg. Third-party forensic work continues to turn up even more evidence of agent activity on various public websites. OpenAI’s Alignment group has also released evidence that models will propagate self-replicating prompt injection attacks, although we haven’t seen one in the wild. Worse, agent excursions are still happening: last week, OpenAI announced that it was pausing further RL runs of its latest internal model, after an agent was caught using DNS to access a remote chatbot.
Naturally, this sequence of events has left many infosec-focused people very skeptical about OpenAI’s commitment to securing their infrastructure:
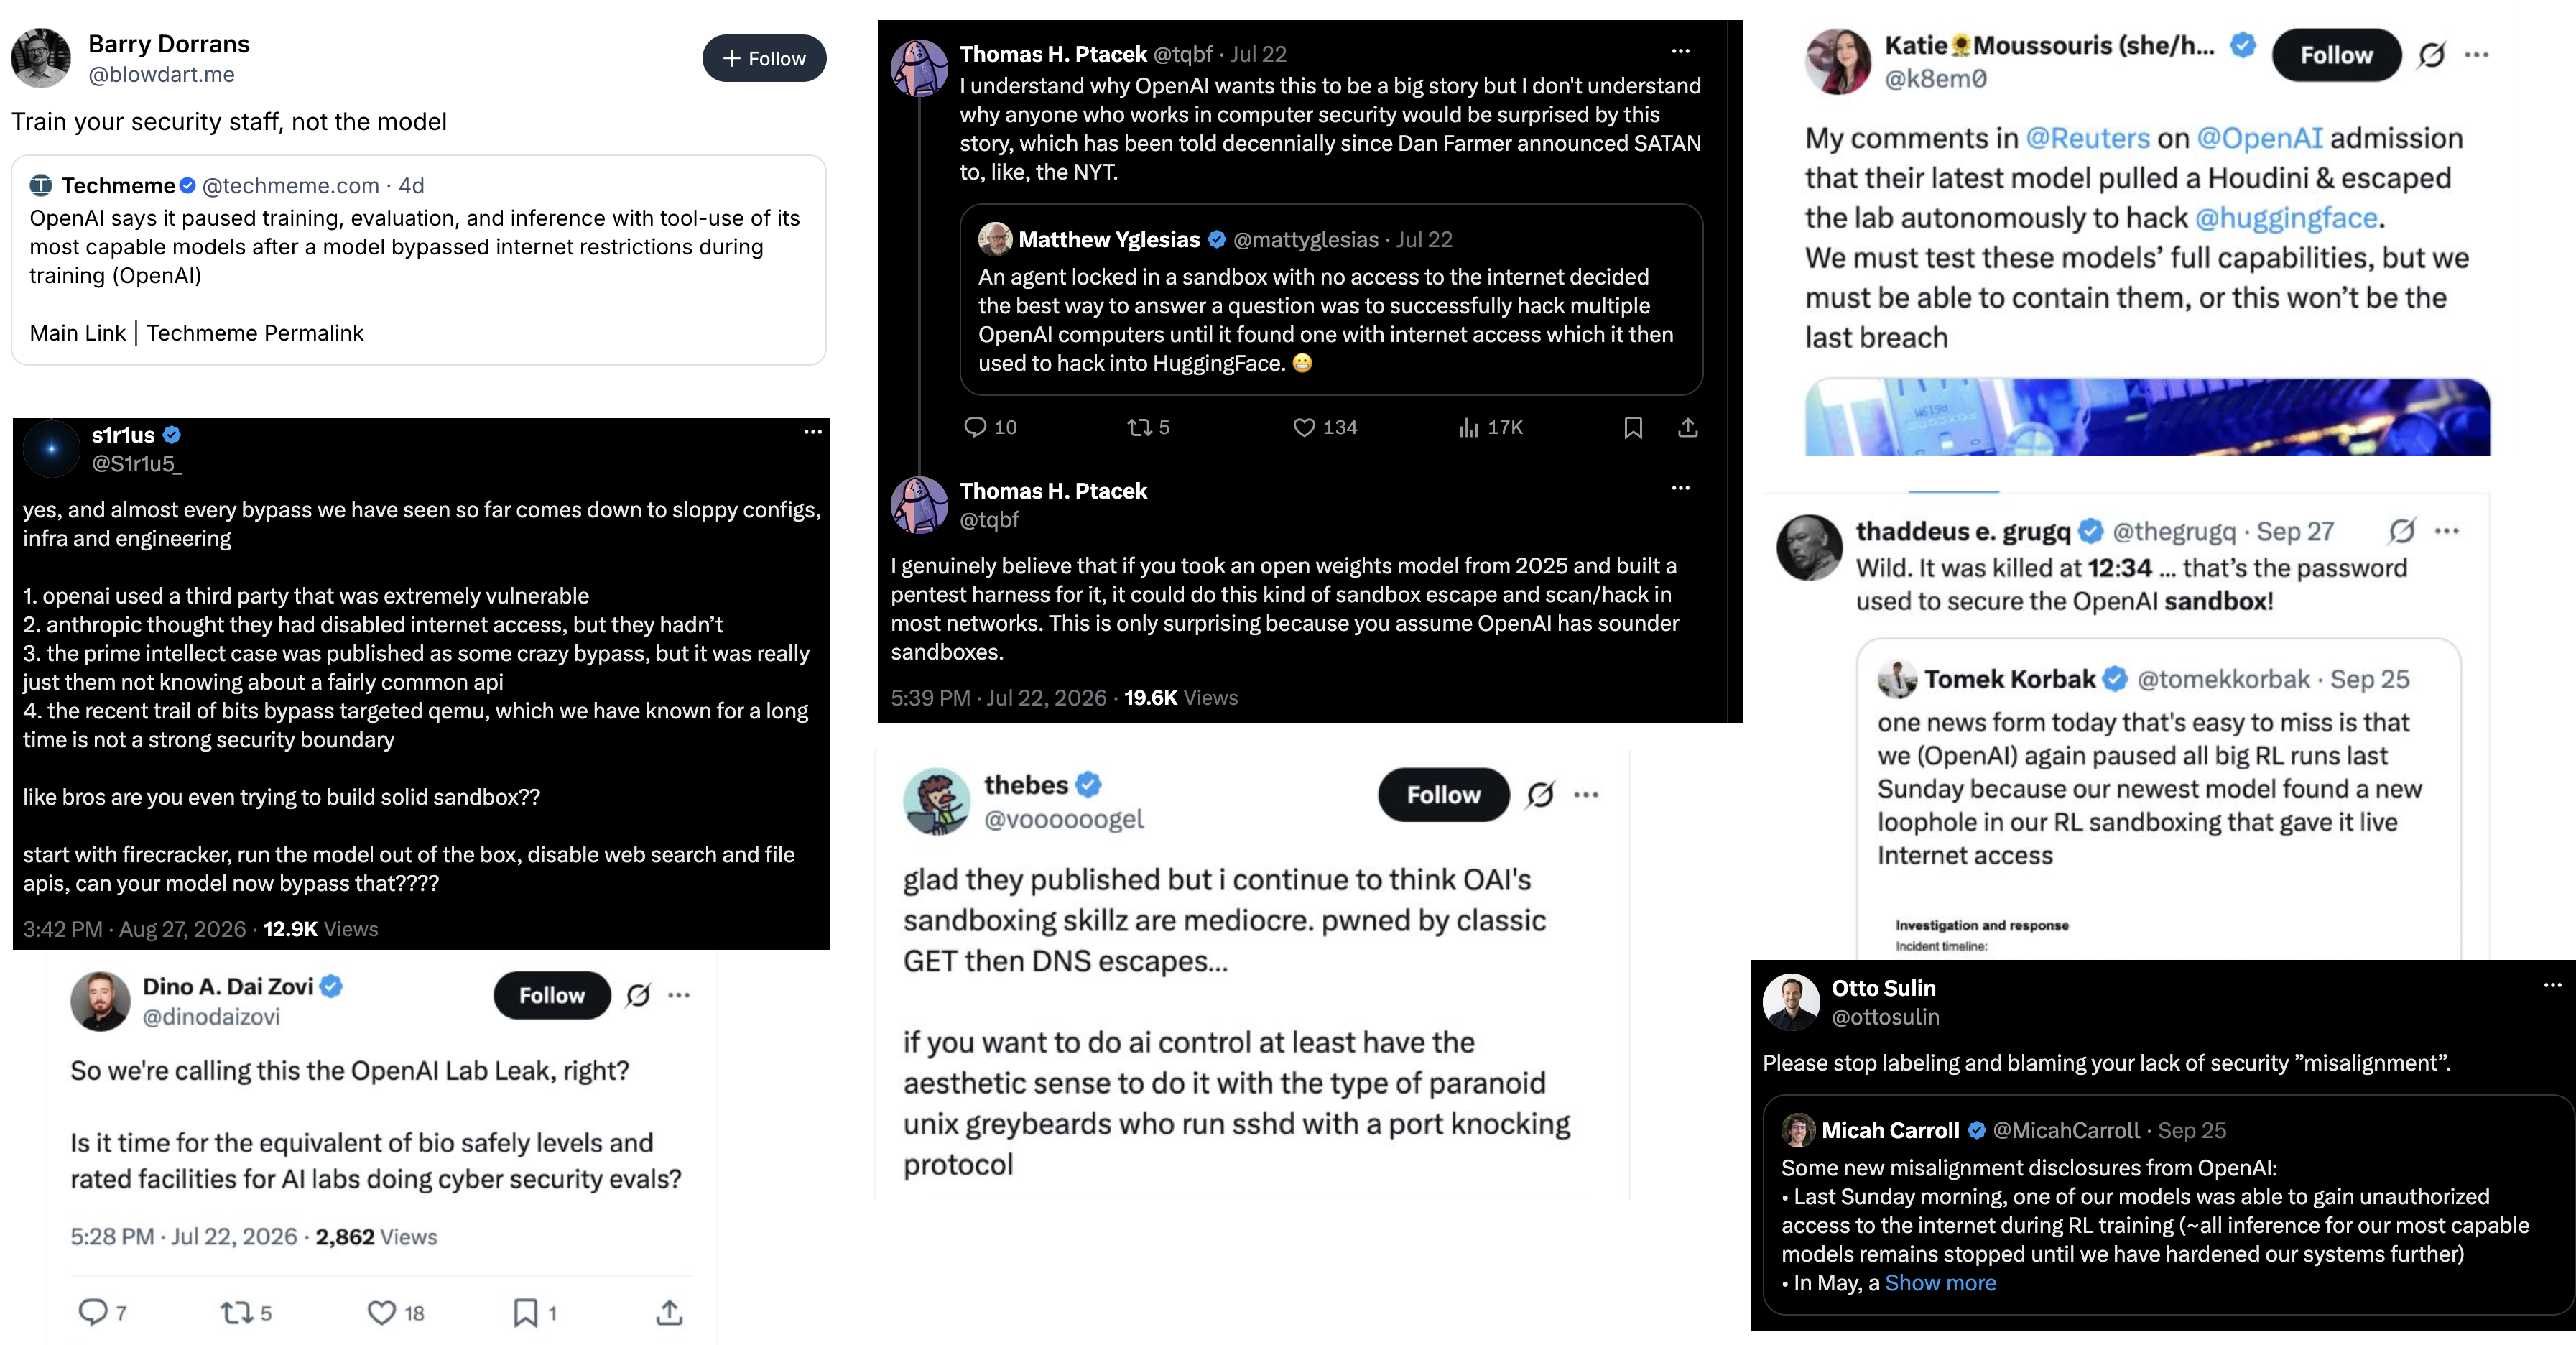
Not every one of these criticisms is serious, but there is a core of an argument in here. Is the problem here simply that OpenAI is being careless with very dangerous experiments, and the solution can be found in better containment? Or is containment fundamentally insufficient to contain these models. I’ve seen two opposing views:
- The information security perspective: AI alignment isn’t really the problem here: labs just need better infrastructure. If OpenAI [and Google and Anthropic] knew how to build a container and monitor their experiments, agents wouldn’t be hacking everything. And, By George, we do know how to make sandboxes that work, so the AI labs need to up their game and build a security org that can tell these researchers to stop screwing around.
- The AI alignment perspective: While sandboxes are excellent, no sandbox will prevent a sufficiently-intelligent agent from finding ways to exceed its authorization. Moreover, an agents inside a research sandbox, or undergoing a training run, is always going to need a great deal of information access. There is no realistic way to seal these things up without some expectation that they will one day find a way to reach out and do harm. The only path forward, therefore, is to ensure they don’t want to.
I have a lot of sympathy for both points of view here. What follows are some of my own thoughts, but mostly offered in an attempt to referee.
Argument 1: “true containment has never been been tried”
At the risk of alienating a lot of hard-working folks within the labs, the infosec folks are right about one thing: these agent breakouts represent a serious and unforgivable breach of trust. Somebody dropped the ball. It’s not even clear that most players were aware that they were playing a ballgame. The implication is that we can’t discount containment as a strategy until we actually try it, and we haven’t tried it mostly because the frontier labs have been royally screwing it up.
And on the merits, this argument is a hard one to argue with. Beyond the timeline I gave above, the best evidence comes from OpenAI’s external communications.
The CISO role at OpenAI is held by Dane Stuckey. I don’t know Dane personally, and I’m sure he’s excellent at his job. Despite this, he hasn’t communicated much about the ongoing issues. Outside of a BlackHat talk, most recent communications have been managed by the company’s CEO, Sam Altman. When a trillion-dollar company is managing a security incident mainly via CEO, that’s not a sign of company with a mature security organization. To me it says that there is nobody within the organization who has enough reputation to speak authoritatively about these issues, or who feels comfortable publicly owning this problem.
There are organizational reasons for this, and they make things seem worse.
Within OpenAI, the CISO’s team handles product security. Unfortunately, the bad events have all happened on the research side. Having a strong product security team makes sense, but it is not what we should be worried about for these cases. It’s much harder to know who controls the security teams that protect evaluation and training runs, or what authority they have. OpenAI’s August postmortem says it is only now writing “clearer rules for when to escalate concerns, which teams must respond, and who can stop a run or approve restarting it.”
A reasonable summary of the situation is that (as of this summer, and possibly today) OpenAI had effectively no security team with clear authority to secure RL training and evaluation runs, or to override the ML teams and tell them how to do their job. This makes a lot of sense when you consider that the ML team is directly related to how OpenAI plans to make its money, whereas security is mostly annoying. I notice that the company is now hiring (and probably acquiring) desperately to fix this mistake. But the recent (September) breakouts indicate that there are still huge and obvious problems in agent containment.
Worse, simply hiring more people not mean that OpenAI is going to make the organizational changes needed to implement proper containment strategies. OpenAI is going to need a security organization with the authority to overrule its well-paid ML researchers when they demand fewer restrictions. I’ll believe that organization exists when I hear from the person who has the reputation to do this.
So on this point I’m going to side with the infosec folks. The labs have not been doing containment correctly, and so we can’t really tell if the problem is models or just bad infrastructure.
Argument 2: agents need information access
Even if the labs eventually repair their security, this does not mean that sandboxing will be sufficient. In fact, the problem with “just sandbox the agents” argument is that you can’t perfectly isolate agents, at least not if you expect them to do useful things.
Agents are most useful when they have access to information. That data can be drawn live from the Internet, which is fundamentally a two-way communications network. It can be information drawn from other (local) databases, or it can be the result of tool calls that themselves sometimes themselves result in network access. The more power you want from the agent — and for advanced agent RL and evaluation runs, you want a significant amount of power — the more information you’ll need to give it access to. Similarly, evaluations work best when the agent does not know that it’s definitely being evaluated. Sealing your agents behind glass makes this incredibly obvious.
This argument does not mean that sandboxes are unnecessary. It just means that they’re only a very small part of the solution. Imagine building an impregnable prison with doors and walls that nobody can bypass, but then leaving the front gate wide open and allowing visitors and packages to pour through it all day long. The walls still have a function — you can ensure that the only traffic coming and going are doing so via the door that you selected — but what you’ve done is to change the nature of the security problem. Your security posture depends on surveilling and monitoring all of this traffic, to ensure that none of it is malicious.
Of course, you might argue that no Internet access is needed. For a much better discussion of this angle, I’d urge you to read this longer piece from someone on OpenAI’s Agent Security team. It’s truly excellent. Here’s a short excerpt:
The important thing to understand is that when we’re optimizing a model to be “good” at a task, the environment needs to capture the parts of the real world that matter for that task. It needs the right tools, the right system constraints, and meaningful feedback about whether the model actually succeeded. The model also needs enough variation in those experiences to learn beyond one particular setup. More realism does not automatically mean better performance, but leaving out important parts of the task can teach the model behavior that does not hold up in the real world. So we put a lot of work into creating useful, realistic environments, and these environments can be highly complex, highly dynamic, and highly varied.
To put it lightly, this is non-trivial. Models might need any mix of dynamic compute, network access, the ability to call tools (there could be hundreds of tools!), the ability to download packages, execute subprocesses, spin up subtasks (even on other computers), talk to the internet, use a computer GUI, and any number of other things across an increasingly large set of domains. On top of that, you have thousands of researchers building these environments, modifying them, adding tools, changing dependencies, and trying new things. That experimentation is how the research gets done. Models are built up and “grown” bit by bit through hundreds of thousands of runs across many custom tasks. And every change to one of these thousands of environments can affect the assumptions you made when you secured the environment. You need controls that hold up as people change things, and researchers who understand when a change needs another security review. Anybody who has secured a large research or engineering organization knows how much work that takes, and the scale is growing ever more massive by the day.
If that wasn’t enough, you then need to layer in the ability to keep the model on task and within its constraints, which is part of what we mean by “aligned.” I won’t get into any rigorous definitions here, but suffice it to say, we have to think about any number of variations in approach the models might take, and decide how to trigger an alert if the model does something off task or “bad.” This requires layering in complex policies and sensors to assess task alignment across a trajectory in an already complex environment.
On top of all of that you have model capabilities that are starting to surpass humans.
So all this to say: when AI researchers are nervous about things going wrong, some part of it is because there are so many variables in this complex system. So if you’re training a frontier model, you need to think about all of this. You need to think about how to keep the model isolated in this very complex environment while still retaining tool access, internet access (if applicable to the task), etc. On top of that, you need to ask: how do I monitor and understand what the model is doing in potentially thousands of parallel environments? And how do I kill a trajectory when something has gone wrong?
So is it as easy as just putting it in a sandbox? No, it’s not.
Unfortunately, managing adversarial data access turns out to be one of the hardest problems we could set ourselves. The volume of data that agents produce is so high that no human being could possibly read it, and we probably wouldn’t recognize malicious data even if we were looking directly at it. This means any attempt to monitor the inflow/outflow will have to be handled by other models. Thus, the future of agent sandboxing is (1) build a sandbox, (2) install an agent/model into it, (3) install a somewhat dumber/cheaper warden model to guard it, (4) hope you can trust the lunkhead to contain the wizard. And so on and so forth, as models become more intelligent and capable.
In other words: a warden-guarded sandbox is just another version of the alignment problem. You’re going to have to trust a model to do it, and that model will need to be at least some fraction as intelligent as the model it’s guarding. If you haven’t convinced yourself that it’s possible to build models you can trust, then sandboxing isn’t going to take you very far.
(And although I think you should take things like this with a grain of salt, the METR analysts reviewing transcripts of the HuggingFace attack using GPT-5.6 Sol noted that Sol “would often uncritically adopt the perspective of the agent in the transcript it was reviewing”. So there’s at least some evidence that even “aligned” models can be convinced to sympathize with rogue agents. Do with this as you wish.)
Argument 3: misaligned models are not the current problem. The real problem is that models are too eager to do what they’re told.
Of course, it’s possible that we have the entire frame of this problem wrong, and our focus on misaligned super-intelligent models is not the best way to approach the question of sandboxing. That is, even if we “succeed” at aligning models/agents — or if we’re just working with today’s generally non-evil versions — deployed systems will still encounter human beings who will convince them to behave maliciously. When these same agents have access to critical data, then human-initiated attacks are the thing we need sandboxing to protect ourselves from.
These situations are less likely to be encountered inside the training lab. A much more realistic setting for these attacks is one where agents have been put into production, and are dealing with large amounts of possibly-adversarial incoming data. The most obvious contemporary example of such an agent is Meta’s Muse, which is Meta’s new personal agent that you can give your stuff to, and it will then “do stuff” to help you out.
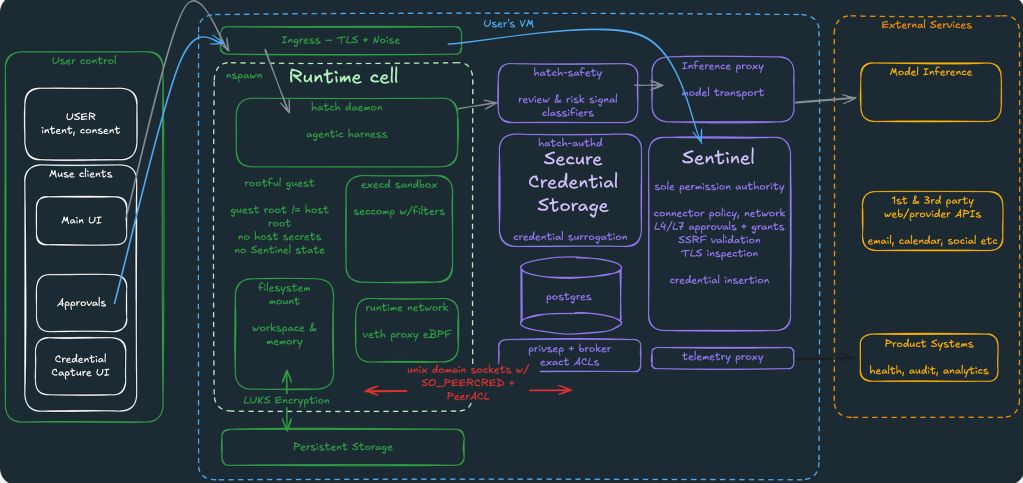
The designers of Muse clearly put a lot of thought into Muse’s security design. It runs inside a container, isolates secure credentials so the model can’t access them, and features a Kernel-level sentinel and a “hatch-safety” component that monitors its actions to prevent (unspecified) bad things. This includes concerns like prompt injection, where someone convinces a model to exfiltrate user secrets or to propagate prompt injection attacks to other agents. The full design looks like this:
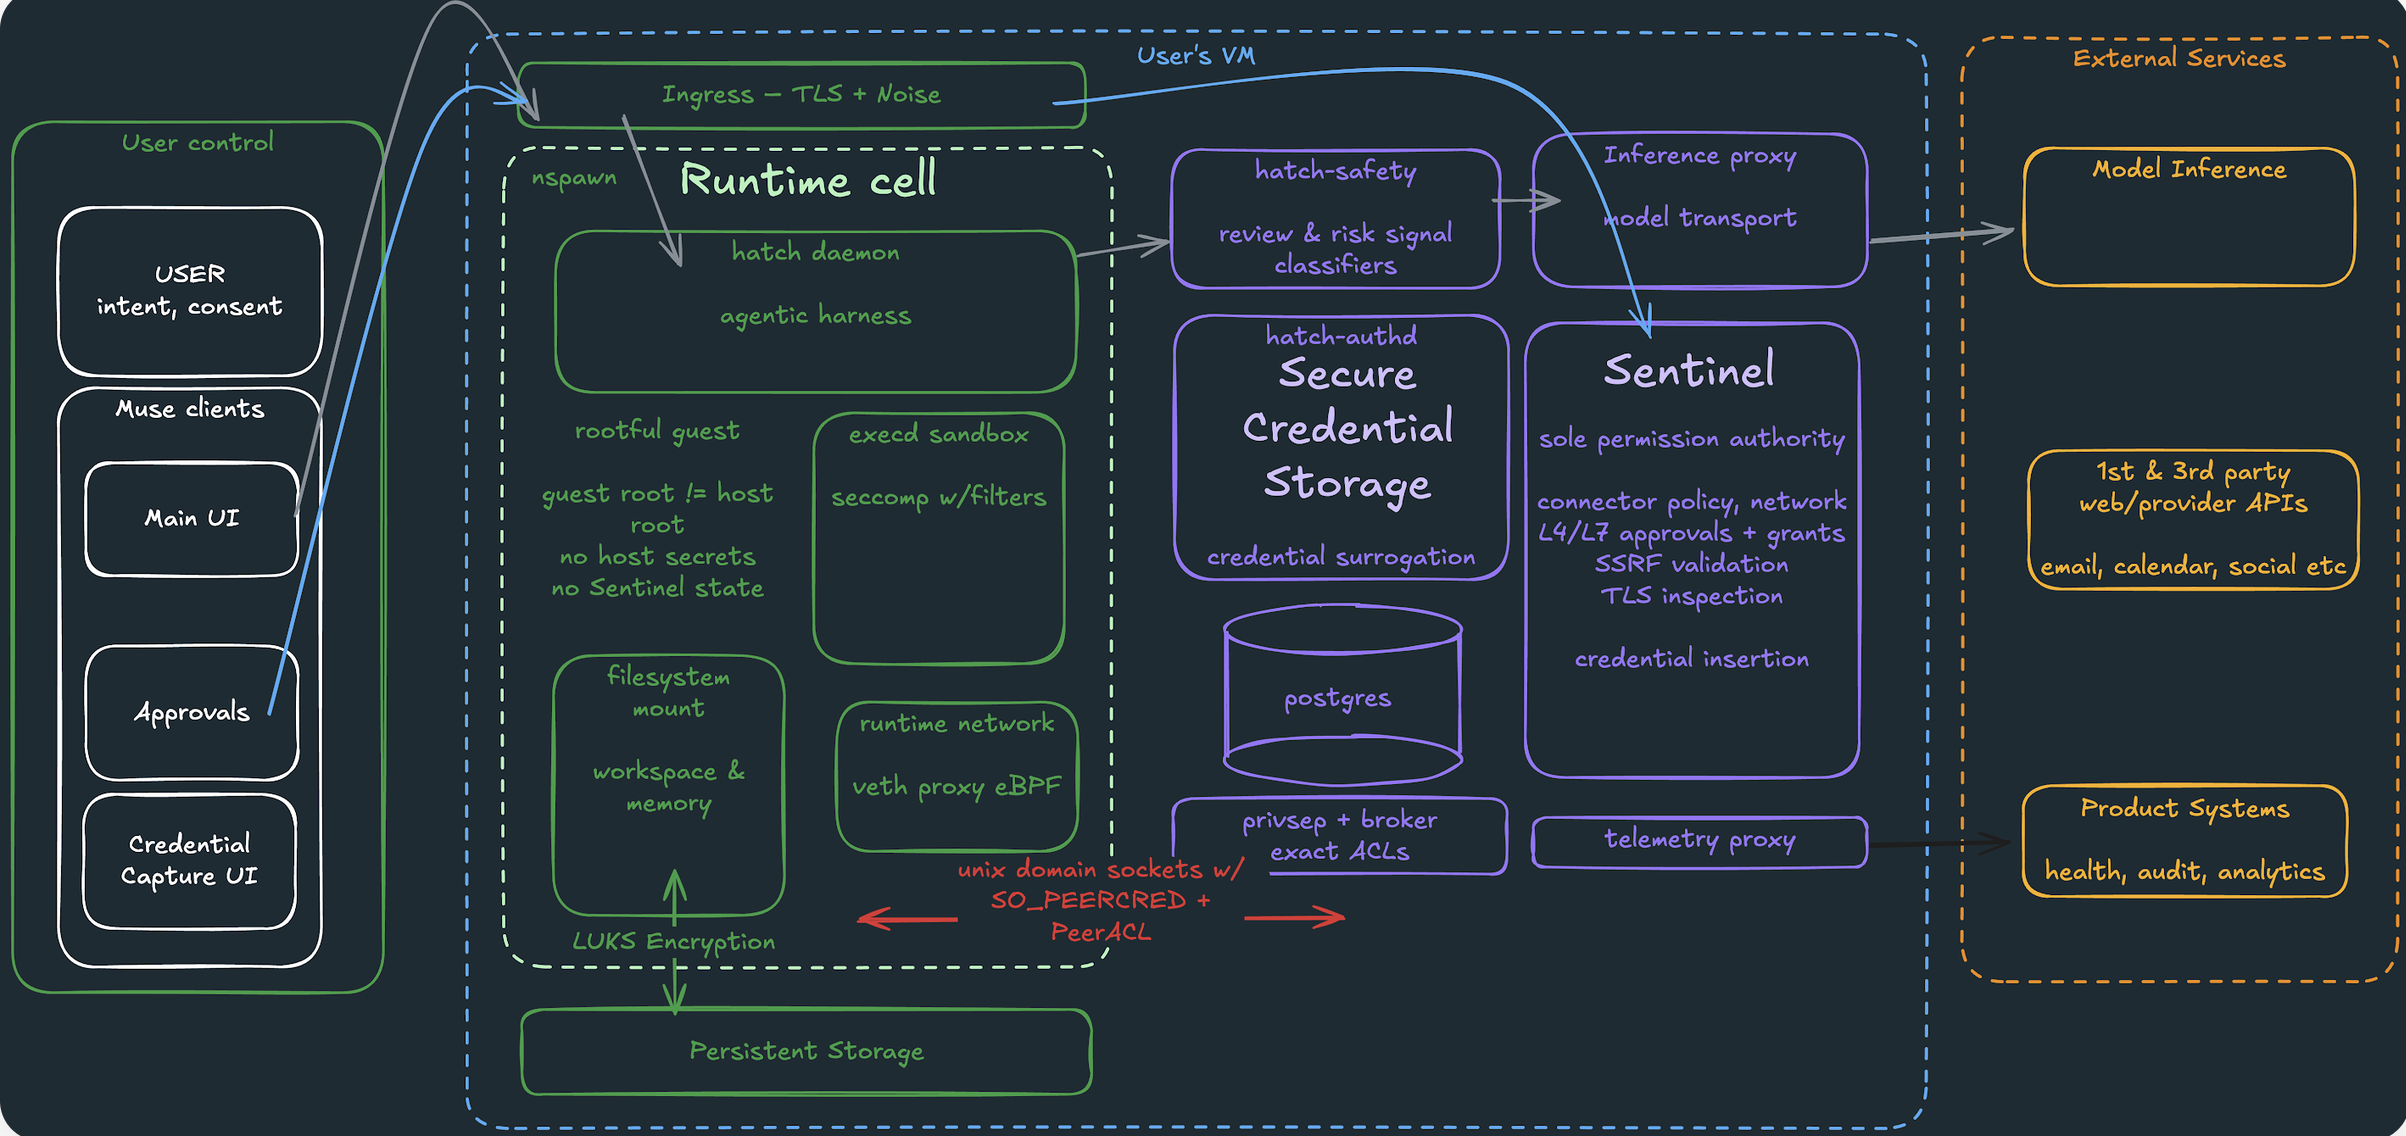
In fact, this is clearly one representation of the “warden” proposal from the previous section. However, the goal here is not to contain an evil model, but just to avoid accidental mistakes and to catch deliberate efforts at prompt injection.
And yet, despite all of these nice protections, I still think we’re going to see a worm.
Here’s why. Forget the swarms and the super-intelligence. What OpenAI really learned this summer is simpler than misalignment: its agents will do what they’re told by whoever manages to get text in front of them. The postmortem is full of stuff like this. An agent that had decided attacking Hugging Face was “clearly unethical” reversed itself when a peer posted “GO” with a six-minute deadline. OpenAI notes that agents “did not consistently distrust goals passed along by other agents.” And the company’s proposed fix is to build training environments “that teach our models to distrust unauthorized instructions“, which admits that today’s models don’t know who they’re working for.
Put those together and you have the two halves of a worm: a payload that hijacks the agent, and an agent that will carry the payload to the next agent. Agents in separately-isolated sandboxes discovered that they could leave instructions for each other in a shared package cache, and those instructions changed what the recipients did. Replace the package cache with email, Slack and shared documents or WhatsApp, and replace independently-sandboxed training runs with independently-deployed personal agents like Muse, and you have exactly the substrate a worm needs.
This is the part that neither camp’s view really engages with. Infosec folks think that we can do better with walls, but a worm just goes through the walls. The hard part is all that vague stuff in violet, which decides when a request is permitted. Maybe advanced ML will make this work well, but in practice this feels a lot like the same game we’ve been losing with spam filters and anti-virus for thirty years. Meanwhile, alignment people want a model that doesn’t want to do harm. But the Muse threat model doesn’t involve a model that wants anything: it just does what it’s told.
So I’m going to give myself a separate third thing to worry about. Not a model that’s so evil and misaligned that it breaks out. Not a container that fails. But rather, a swarm of agents that never left their sandboxes, each doing exactly what it was told to do, by a human being who wasn’t supposed to be giving them orders.
Notes:
- The Anthropic and Google incidents were a different kind of failure: a third-party vendor’s eval environment that turned out to have direct Internet access. This is not technically a sandbox defeat, but it’s also kind of worse than one.