Say you run support for a bank. A customer opens the chat and asks:What are the terms of the family 2026-9-27 13:13:49 Author: hackernoon.com(查看原文) 阅读量:2 收藏
Say you run support for a bank. A customer opens the chat and asks:
What are the terms of the family mortgage?
You have to answer. Instead of reaching for a framework or the "ideal" RAG diagram, let's just build it. Start with the simplest thing, and fix each part when it breaks.
You have to answer. Instead of reaching for a framework or the "ideal" RAG diagram, let's just build it. Start with the simplest thing, and fix each part when it breaks.
What answering needs
To answer that one question, you do two things:
- Find the internal document with the answer.
- Use that document to write the reply.
That is the whole system. One half searches. The other half answers.
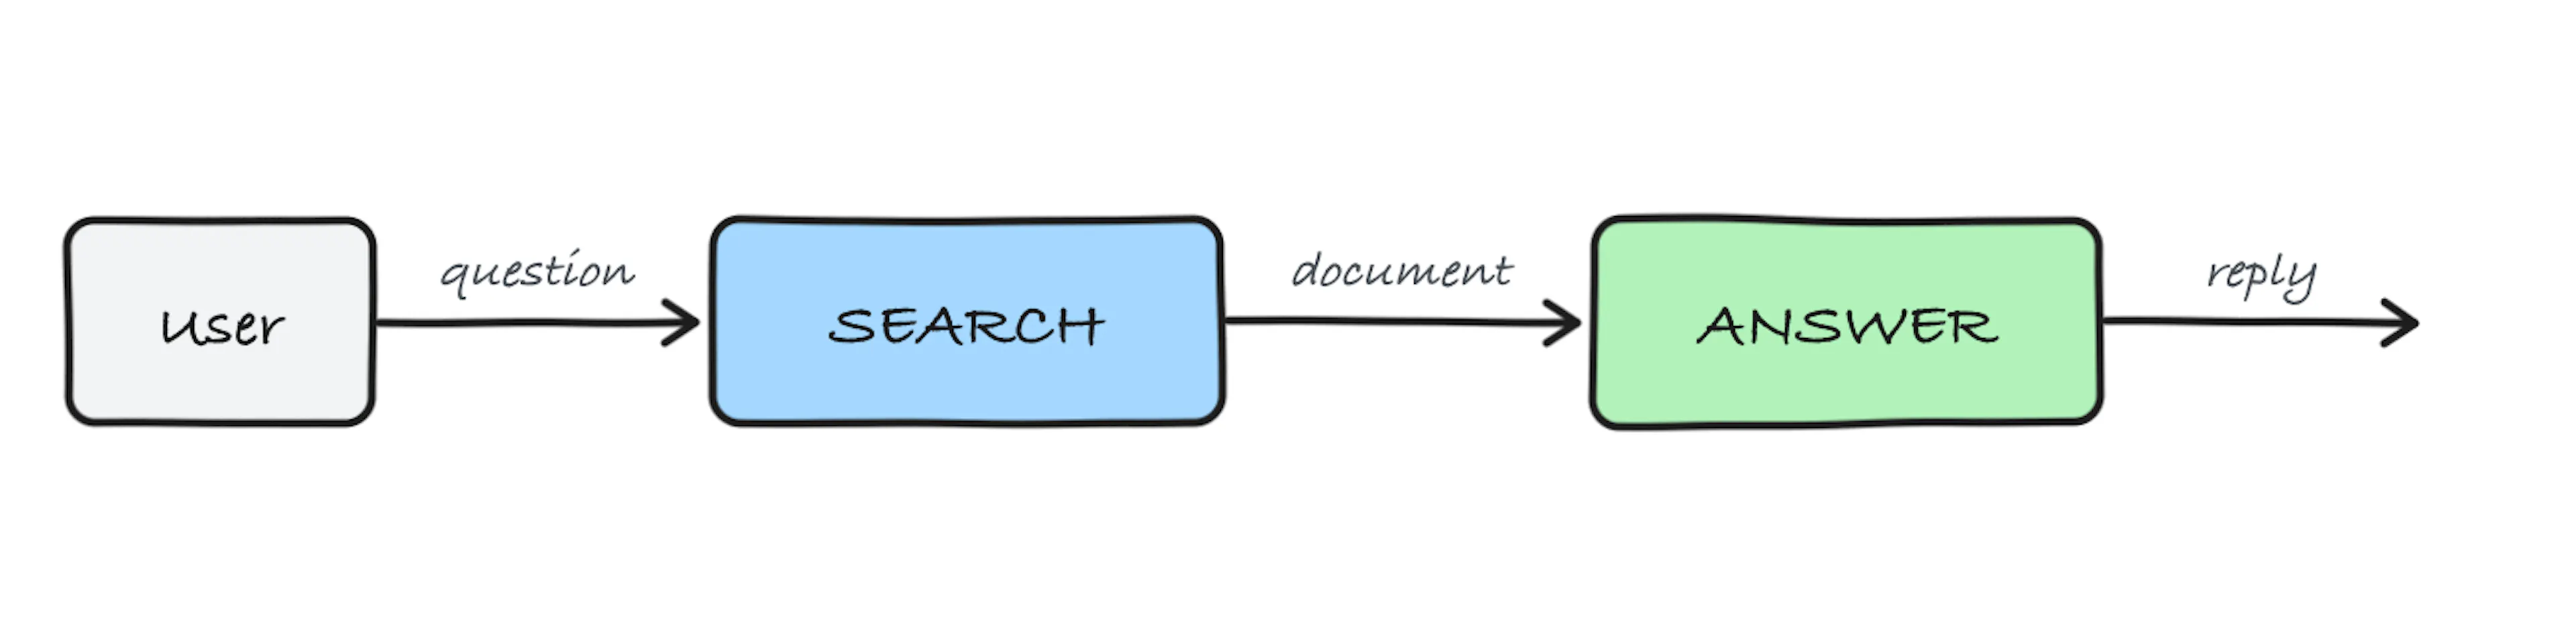 The system splits in two: a search half that finds the document, and an answer half that writes the reply.
Start with the answer half. It is easier.
Part 1: Answering (the easy half)
Assume search already works and gives you the right document. Then you just build a prompt:
<System>
You are Mark from support. Answer the customer's question using only the reference below.
If the reference doesn't contain the answer, say you don't know.
</System>

<Query>
What are the terms of the family mortgage?
</Query>

<References>
{the document search returned}
</References>
Send this to an LLM. A small open model is enough. I run Qwen3-8B with vLLM. That is the whole answer baseline. Done.
Search is the interesting part.
Part 2: Retrieval (the interesting half)
First, one question about your users. Do they only ask general things, like rates, deposit terms, or how to close an account? Or do they also ask about their own money, like one account or a transaction that has not cleared yet?
The answer is both. This matters, because it splits the system into two search paths:
- Reference data: rate sheets, product terms, promotions. The same for everyone.
- User data: this customer's accounts, transactions, loans. Private to them.
Start with the reference path.
Start simple: BM25
The simplest search that works is keyword search. BM25 is the standard choice. For each document you build a sparse vector, close to TF-IDF. Rare words get more weight. Words that appear in almost every document get almost none. Before that, clean the text: remove punctuation, normalise word endings, lowercase.
This works for a while. Then it stops.
Where BM25 breaks: meaning
Say someone searches for beautiful non-earthly creatures. BM25 gives almost the same score to a document about ugly earthly creatures, because the words overlap. The meaning is the opposite, but keyword search cannot see that.
So you add semantic search. You encode the query with a sentence embedding model and look for the nearest documents in vector space. With E5, for example, you add a prefix (query: for the question, passage: for the documents) and compare vectors. You store the vectors in Qdrant or Chroma, or use a framework like LlamaIndex to set it up.
Now paraphrases and near-synonyms match too, and BM25's blind spot is covered.
Preparing the knowledge base: chunking
Semantic search is only as good as the chunks you give it. Split documents by their structure, usually by paragraph, so each chunk is one full idea.
Watch the token limits. Many encoders take 512 tokens at most. Some, like BGE-M3, take up to 8k. But think about how much meaning is left when you squeeze 8k tokens into one vector. The longer the chunk, the blurrier the embedding. Pick the chunk size with this trade-off in mind, not after.
Combining both: RRF
Now you have two ranked lists: one from BM25, one from the encoder. You need to merge them. Reciprocal Rank Fusion (RRF) is a simple, solid default. Each document gets a score from its rank in each list, and you add the scores.
RRF is not perfect. A chunk that shows up in only one list can land too high or too low, because there is nothing to fuse it with. It is good enough to move on. Just remember it when the results look off.
Reranking: the cross-encoder
The last step is a cross-encoder. It helps to see why it differs from E5.
E5 is a bi-encoder. It encodes the query and the document on their own, into two vectors, and compares them. Anything that did not fit into a vector is lost before the comparison.
A cross-encoder takes the pair query: … document: … as one input. From the first layer it sees the query and the document together. It runs attention over both and passes them through the network. It is slower, so you do not run it on the whole corpus. You run it on the top results from RRF and reorder them. Much of the final quality comes from this step.
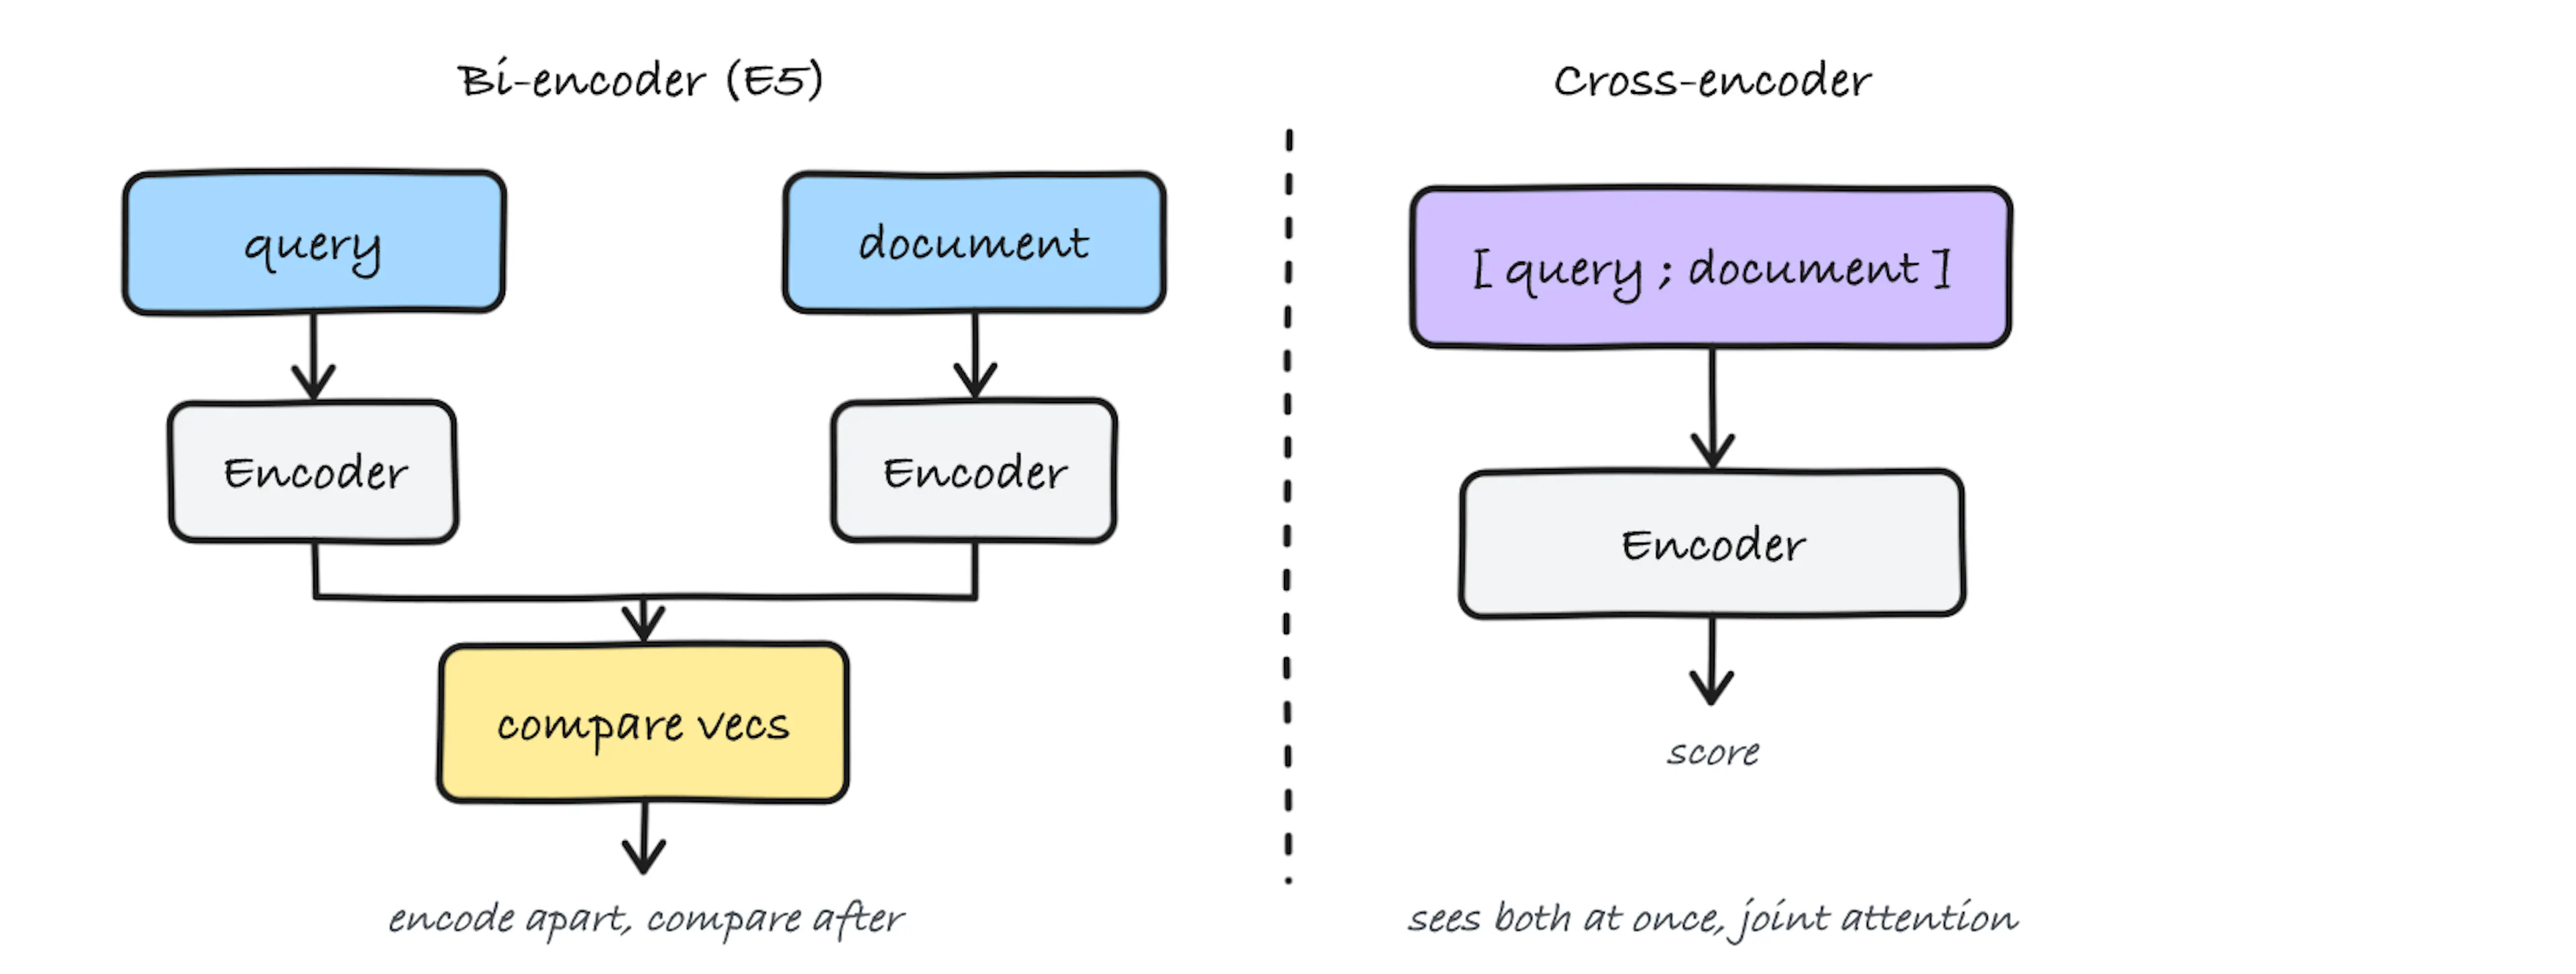 Bi-encoder encodes the query and document into separate vectors and compares them. The cross-encoder reads both together and scores the pair directly.
So the reference path is: BM25 + dense retrieval, merged with RRF, reranked by a cross-encoder.
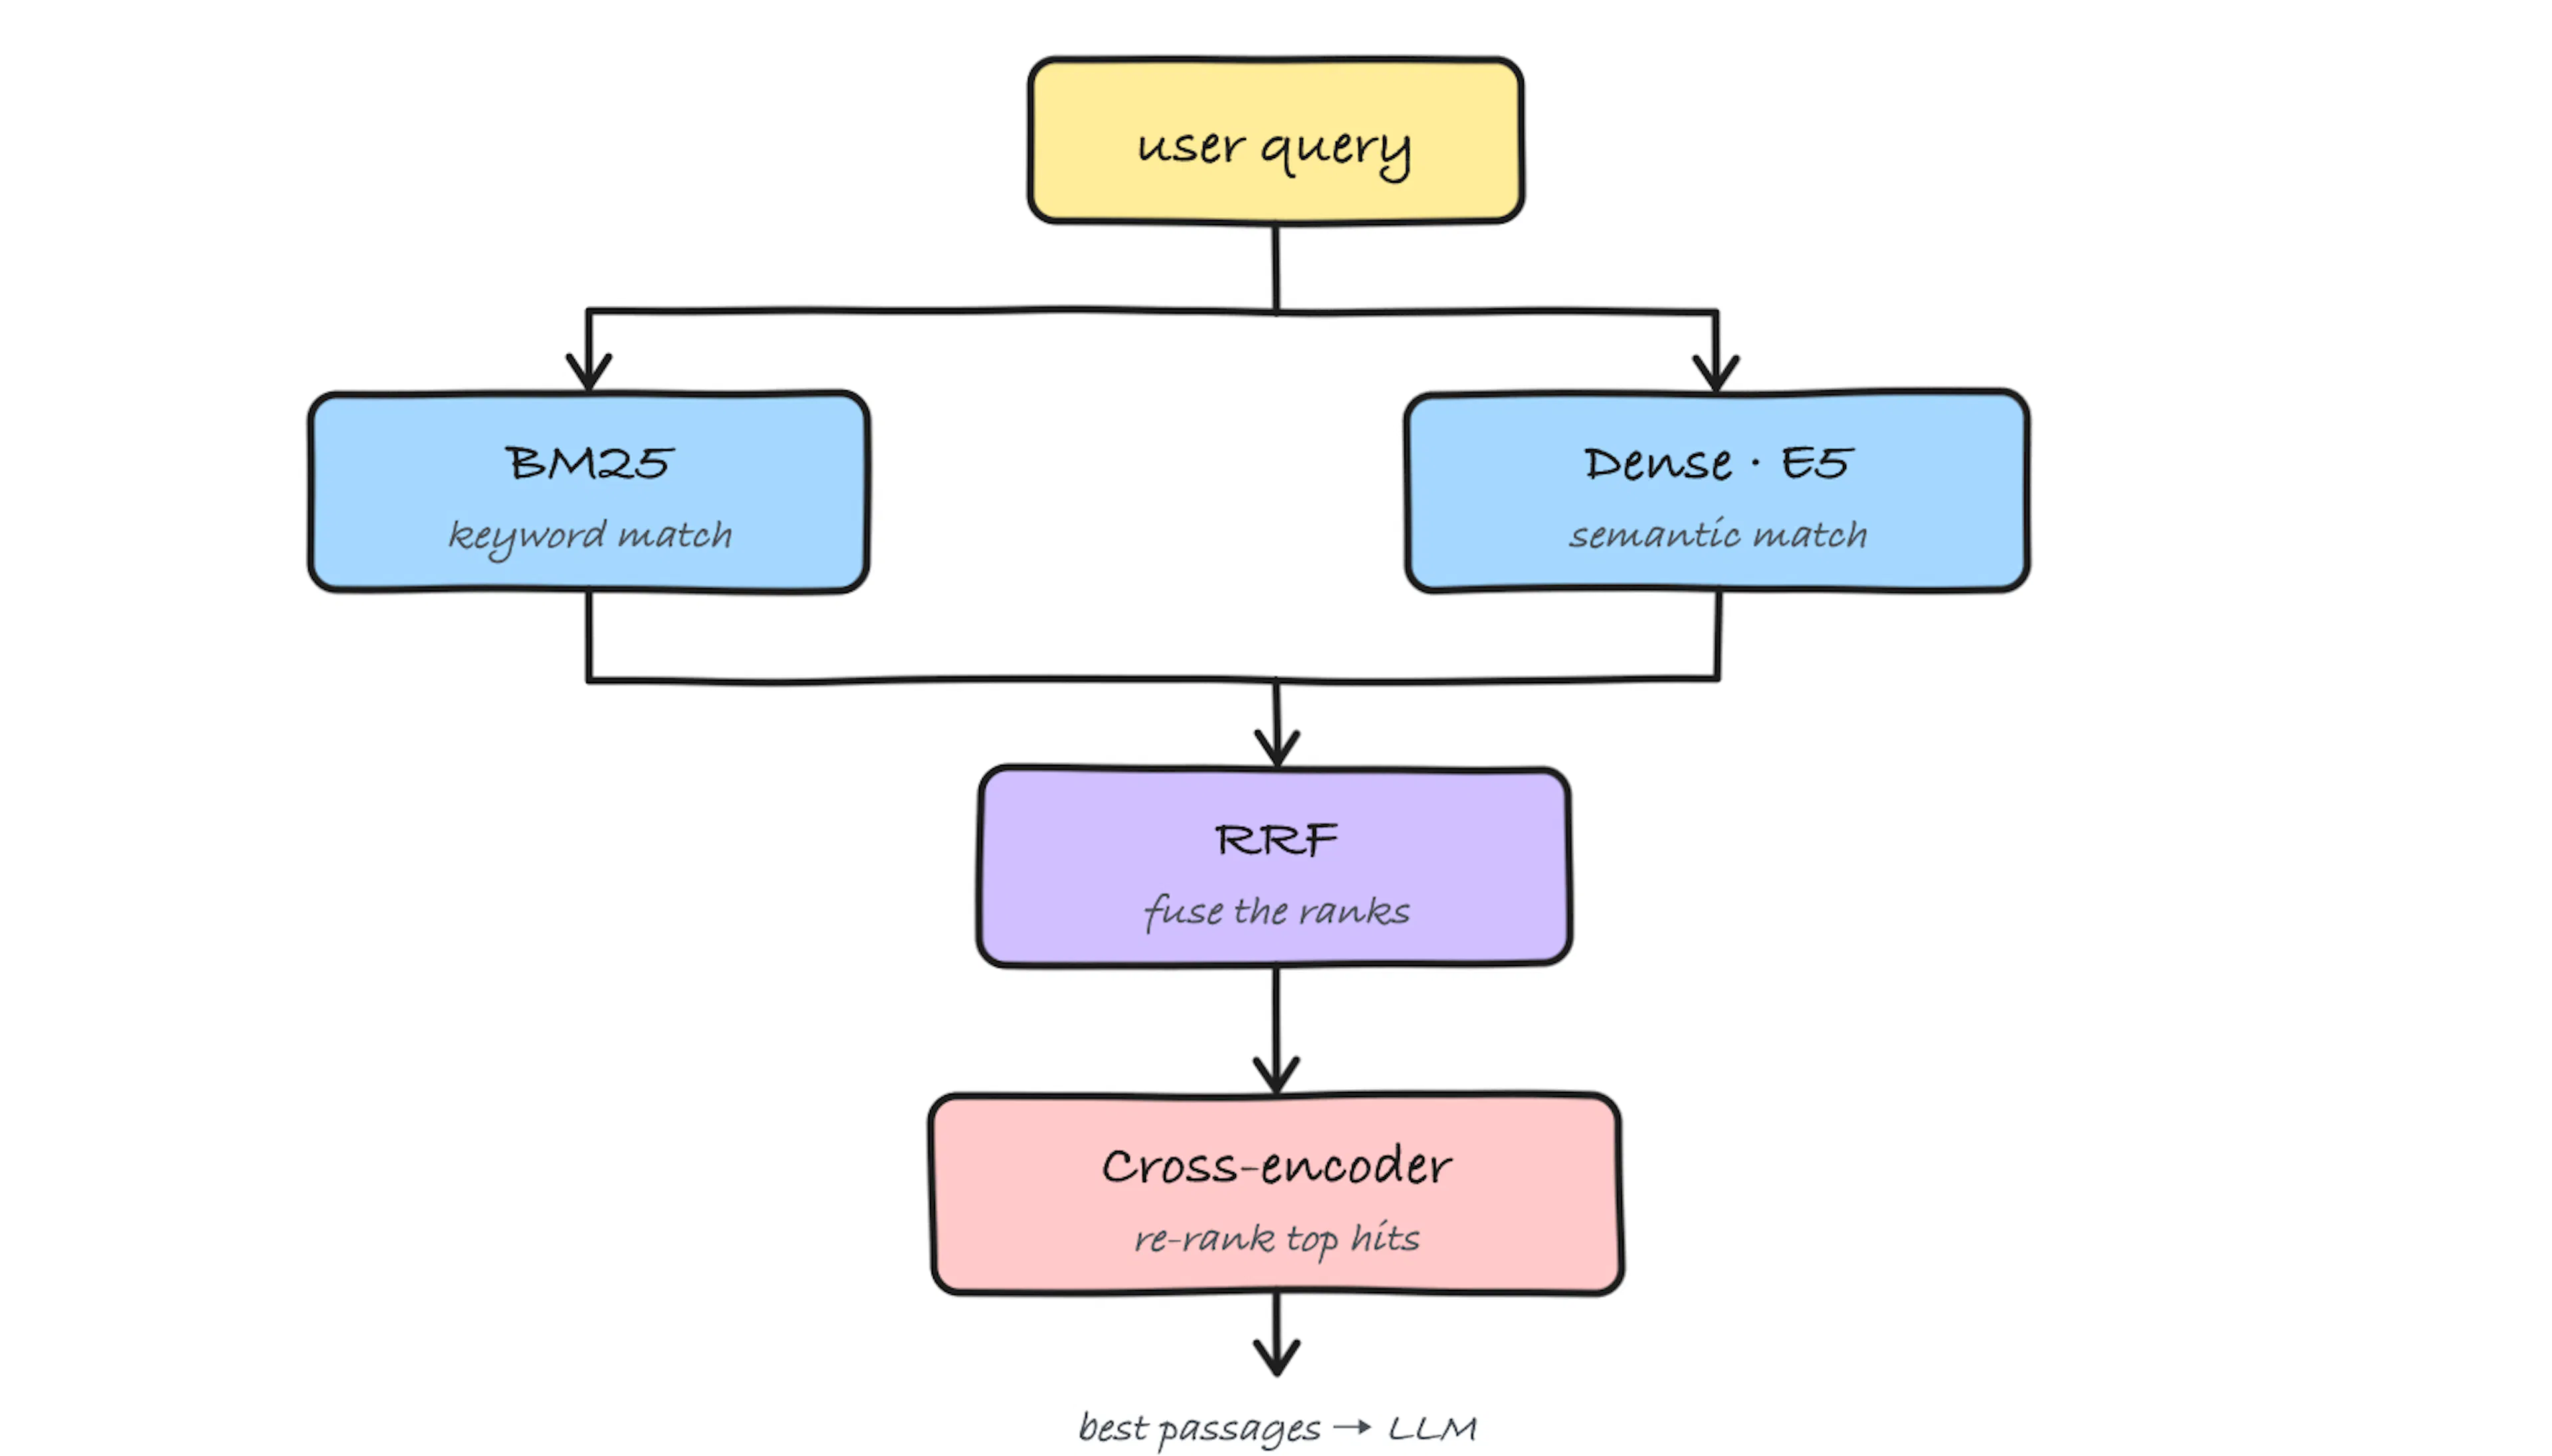 Bi-encoder encodes the query and document into separate vectors and compares them. The cross-encoder reads both together and scores the pair directly.
Part 3: The customer's own data
Now the second path. This one is harder. After the first message, the system decides if the question is about the customer's own accounts, transactions, or loans. Then it reads live data.
Security comes first
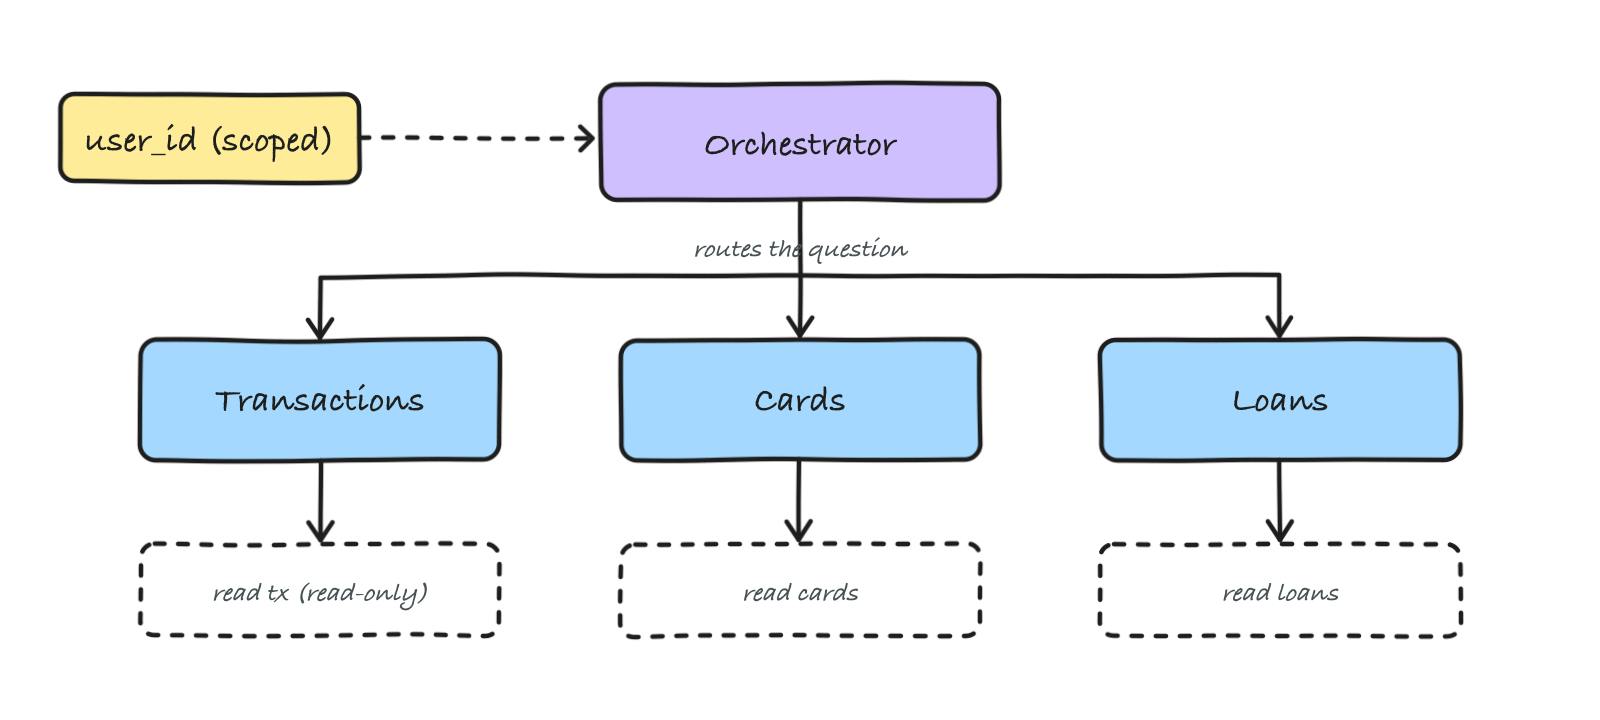
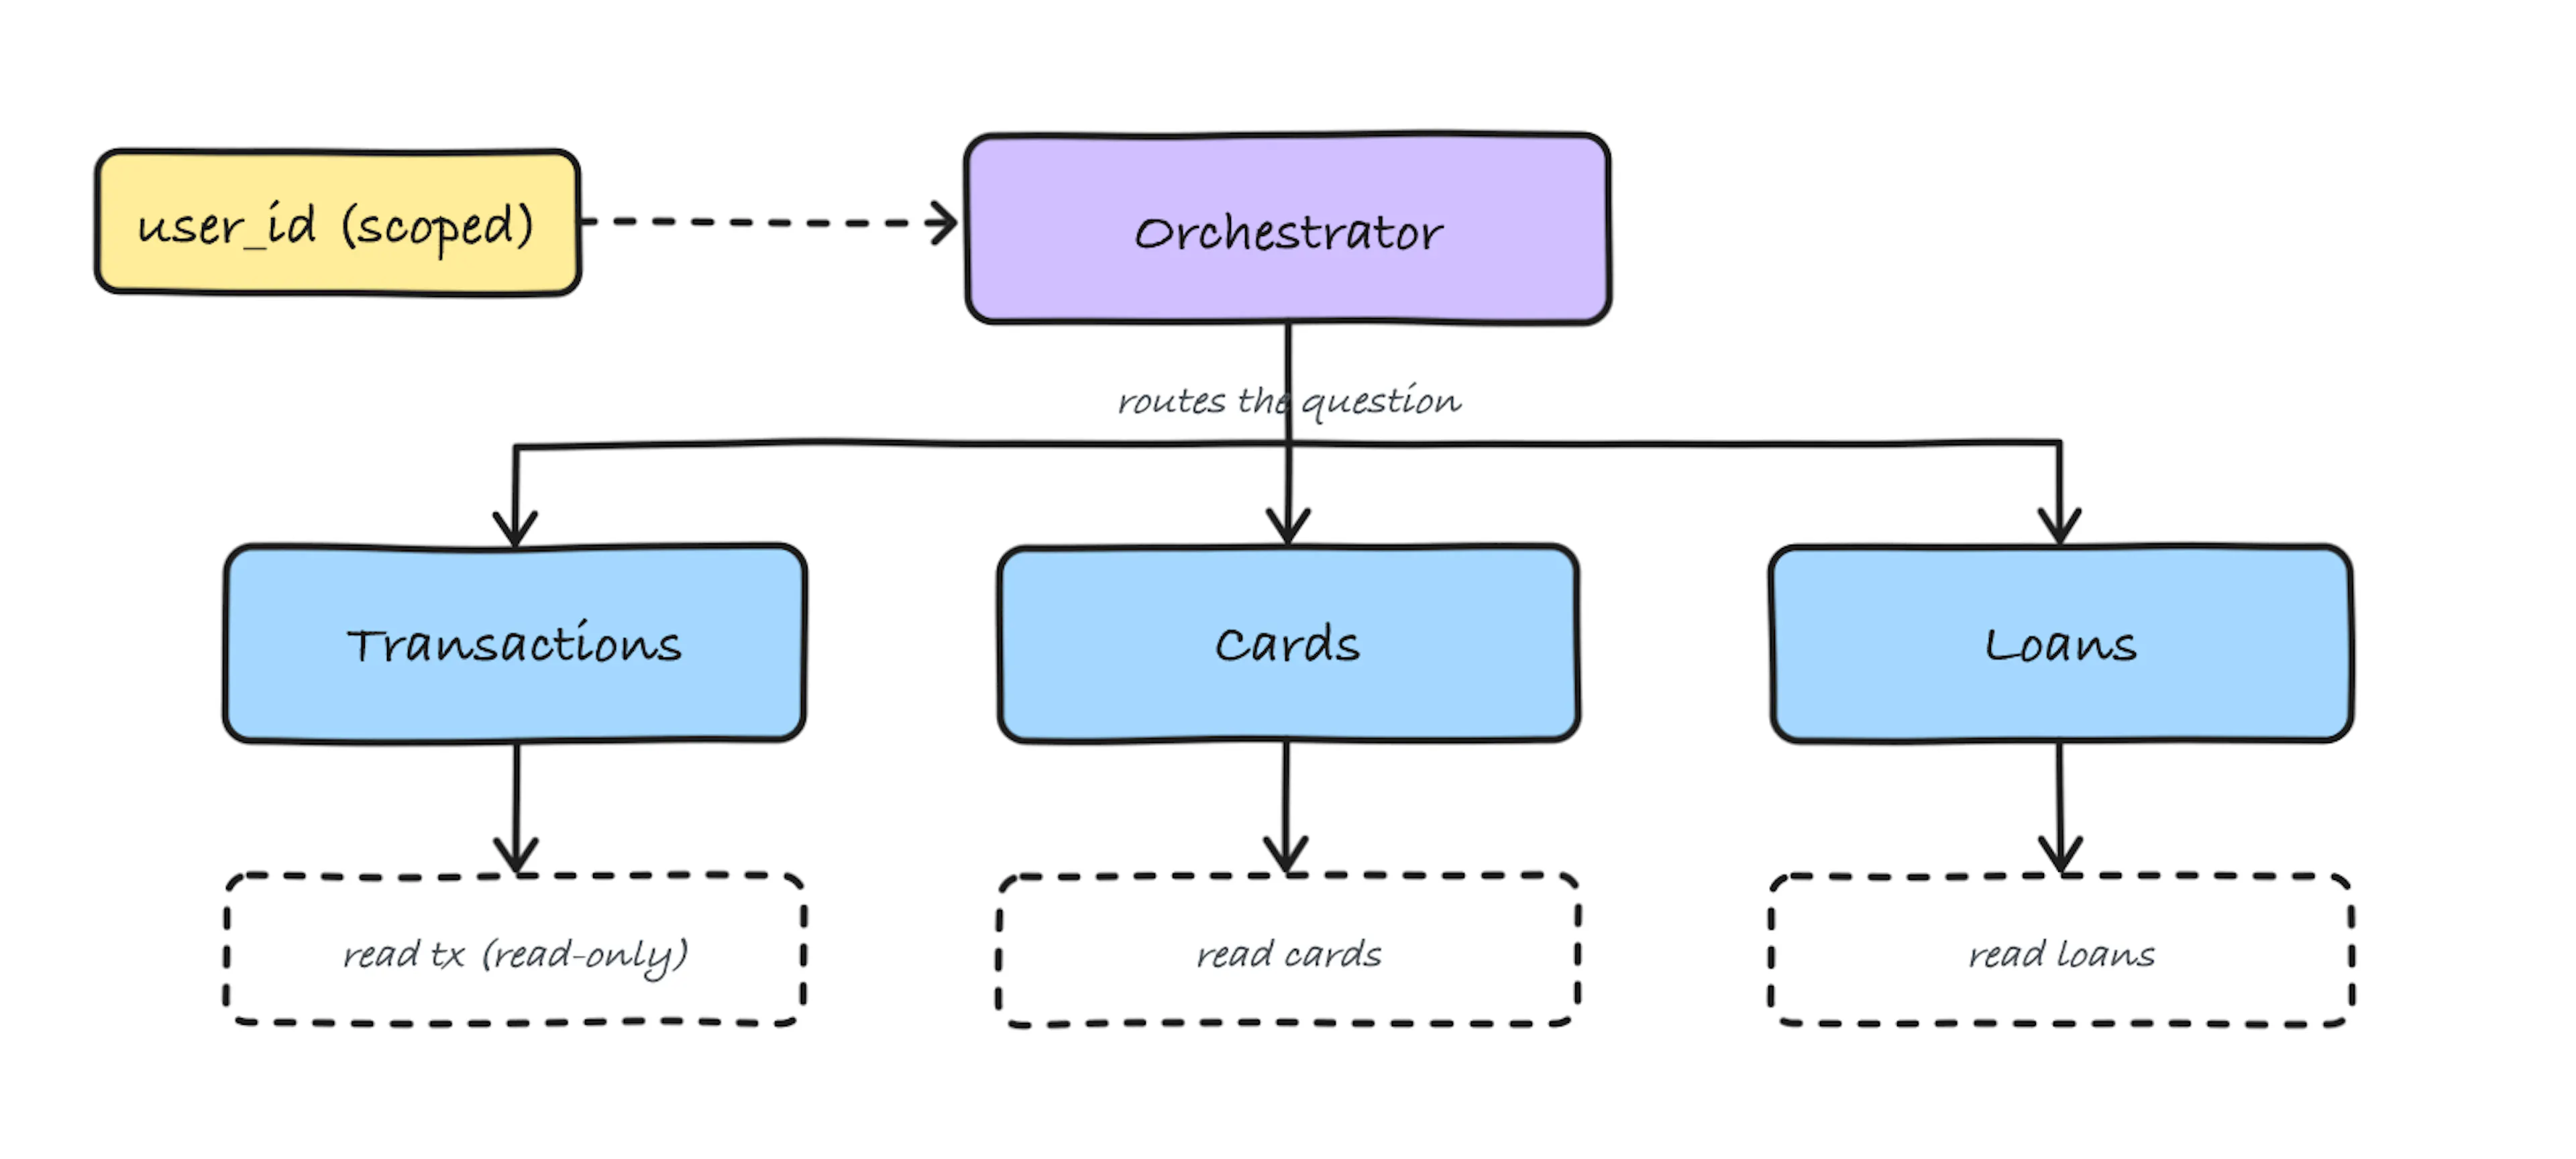
One rule beats all the others here: a session must never see another customer's data. Before any architecture, fix the identity. Pass user_id through the agent's injected state (the InjectedState / configurable pattern in LangGraph) and scope every tool call to that id. The agent can only read data for the person it is talking to.
Get this wrong and nothing else matters.
One agent or several?
Do you need many agents, or is one agent with a few tools enough? It depends on how different the questions are. One agent with tools like "look up account", "list recent transactions", and "check loan status" covers a lot. It is also easier to reason about and cheaper to run.
Add more structure only when one prompt cannot hold all the tasks.
Hierarchical multi-agent
When that happens, the common shape is a hierarchical multi-agent system. You build small sub-agents. Each one has its own tools and system prompt: one for transactions, one for cards, one for loans. An orchestrator reads the question and sends it to the right sub-agent. Each sub-agent stays small and easy to test. The orchestrator handles the routing.
 Bi-encoder encodes the query and document into separate vectors and compares them. The cross-encoder reads both together and scores the pair directly.
Design the tools on purpose
An agent is only as safe as its tools, so design them with care. Do not just expose whatever the backend has. For each tool, be clear if it reads or writes. Reads are cheap and easy to undo. Writes touch real money, so they need stronger checks and usually a human in the loop before they run.
Give each agent a small role and only the tools it needs. A transactions sub-agent should not hold a "close account" tool. And watch all of them: log every routing choice, every tool call, and every answer, so you can see which agent did what when something breaks.
Do not judge quality by reading a few chats. Build an eval harness: a set of real questions with known-good answers that you run the pipeline against, so retrieval, tool choice, and answer quality all get a number. This is a big topic on its own, so I will cover it in a later article. For now, just know that without it you are guessing.
Part 4: Combining retrieval and agents
Now the two halves have to work as one system. The reference path and the personal-data path answer different questions, so something has to pick the right one.
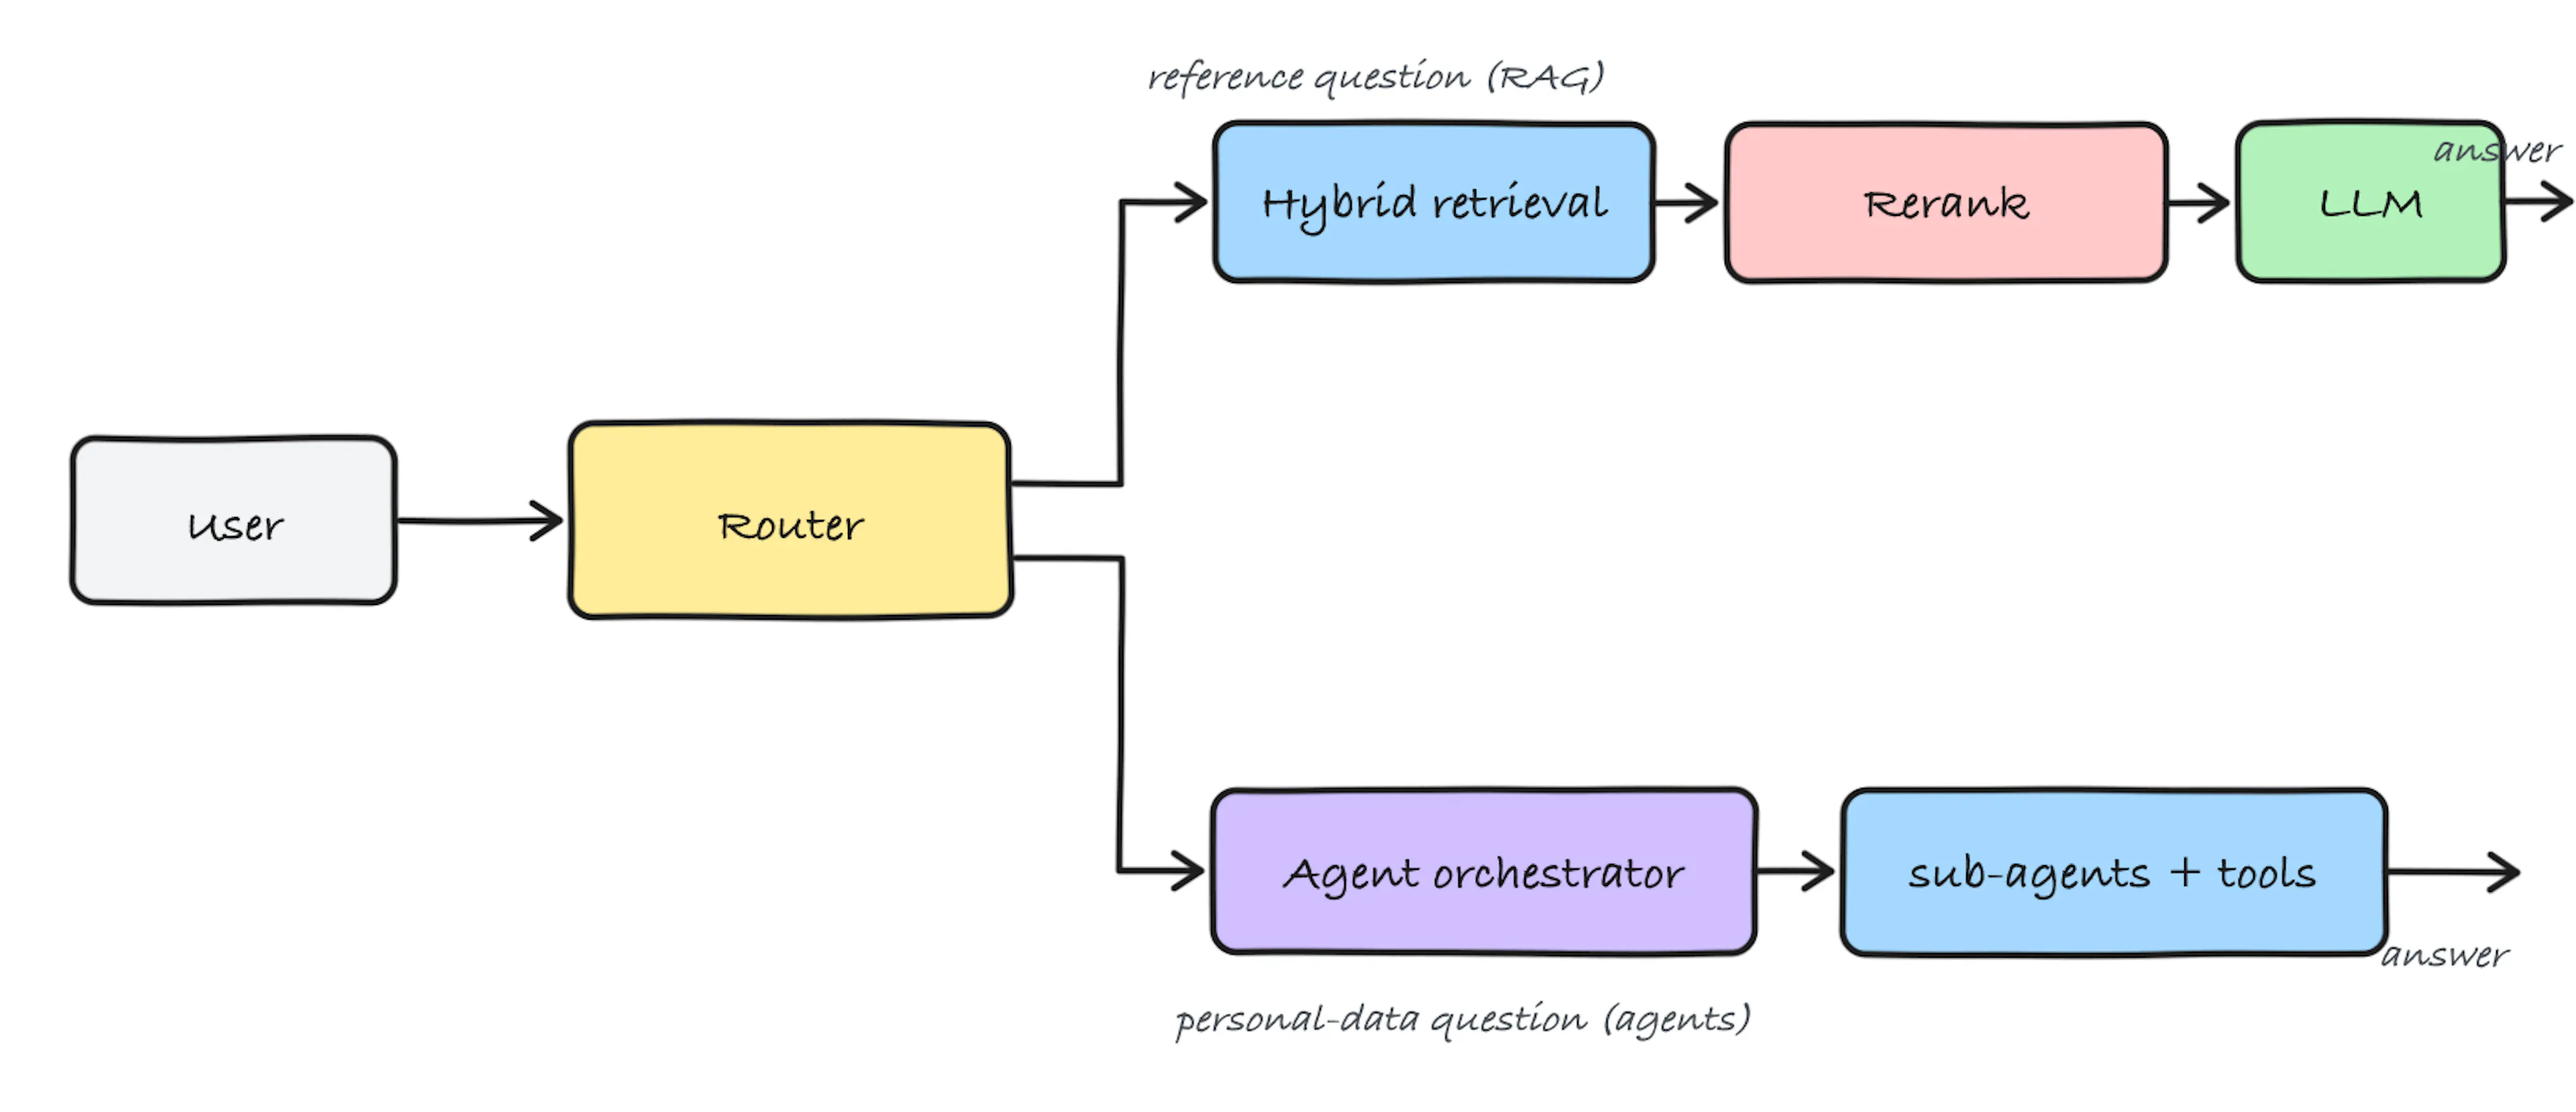
The simplest way to join them is a router. A small classifier, or a short LLM call, reads the message and sends it to the right path: the hybrid retriever for reference questions, the agent for personal-data questions, or both when the question needs both. The router is just another part of the system, so it goes into the logs and the eval harness too.
The shape of the system
 Bi-encoder encodes the query and document into separate vectors and compares them. The cross-encoder reads both together and scores the pair directly.
Put the two paths together and the system looks like this:
- A router decides if the question is about reference data or the customer's own data.
- Reference questions go through hybrid retrieval: BM25 and dense retrieval, merged with RRF, reranked by a cross-encoder, then answered by the LLM.
- Personal questions go to an identity-scoped agent (one agent, or a hierarchy when there are many tasks) that reads live data and answers.
None of these parts is fancy. What matters is the order you add them. Build the dumb version. Watch it fail on a real question. Then add the one piece that fixes that failure. That is how you get a retriever you actually understand.
如有侵权请联系:admin#unsafe.sh