
AI-powered fuzzing with the GitHub Security Lab Taskflow Agent
If you’re new to fuzzing and want to learn the fundamentals first, check out our Fuzzing 101 cour 2026-9-24 18:27:17 Author: github.blog(查看原文) 阅读量:3 收藏
If you’re new to fuzzing and want to learn the fundamentals first, check out our Fuzzing 101 cour 2026-9-24 18:27:17 Author: github.blog(查看原文) 阅读量:3 收藏
If you’re new to fuzzing and want to learn the fundamentals first, check out our Fuzzing 101 course at gh.io/fuzzing101.
Continuous fuzzing is not a magic solution that solves all your problems . Even projects that have been enrolled in OSS-Fuzz for years can still hide critical bugs, and the reason is almost always the same: someone needs to keep an eye on coverage, write new harnesses for the code that nobody is reaching, and triage the crashes that come out the other end. In other words, fuzzing still needs a human in the loop.
So the natural question I kept asking myself was: how much of that human work can we actually hand over to an LLM agent?
That is what led me to build the Fuzzing Taskflow, an autonomous fuzzing pipeline for C/C++ projects. You only need to point it at a GitHub repository, and it does the rest: it identifies the suitable entrypoints, analyzes the build system, writes the harnesses, runs AFL++, reads the coverage reports, improves the harnesses, triages every crash, and writes a vulnerability report for each unique bug, all without a human babysitting it.
The Fuzzing Taskflow is built on top of the GitHub Security Lab Taskflow Agent, our framework for writing LLM-driven security automation, so the pipeline is expressed as a set of taskflows that an agent runs end to end.
In this post, I’ll walk you through how it works and the design decisions behind it. Let’s get going!
How to run it
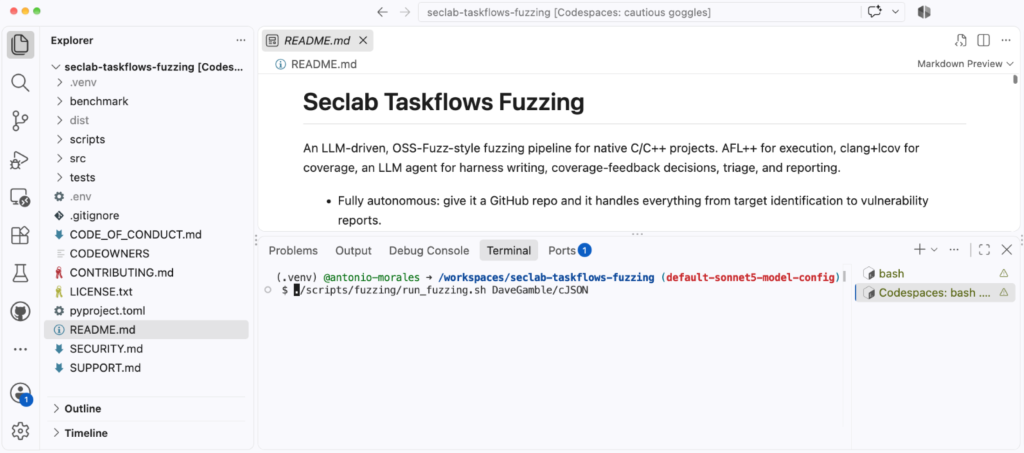
The simplest way to run it’s just to go to https://github.com/GitHubSecurityLab/seclab-taskflows-fuzzing and start a codespace.
Then, run the script like this:
./scripts/fuzzing/run_fuzzing.sh PROJECTSo, for example:
./scripts/fuzzing/run_fuzzing.sh tukaani-project/xzThat’s it. The argument is just a GitHub owner/repo slug. Then, the agent, takes care of all the preliminary steps on its own:
- Installing software such as AFL
- Cloning the repository
- Identifying the most relevant functions in the code
- Creating fuzz targets for those functions
If you just want a quick smoke test before committing to a long campaign, point it at something small:
./scripts/fuzzing/run_fuzzing.sh DaveGamble/cJSONA word of warning before you run it: this taskflow runs afl-fuzz, clang, and arbitrary build commands chosen by the LLM directly on the host, with no container in between. A prompt-injected agent could, in principle, do anything your user can. So please run it only inside a disposable environment (e.g., a Codespace or a throwaway VM), without elevated privileges.
Model selection
Some frontier models impose security guardrails on their outputs. For the fuzzing task flow, we use Claude Sonnet 5 by default because it passed all of our internal tests without issues. You can choose a different model by modifying the following file: src/seclab_taskflows_fuzzing/configs/model_config.yaml.
The architecture in one minute
Before getting into the interesting parts, it helps to know how the pieces fit together. There are three layers:
- A shell driver (run_fuzzing.sh) that chains the pipeline stages together.
- A set of taskflow YAMLs, one per stage, which are essentially the prompts that tell the LLM agent what to do at each step.
- A set of MCP tools that the agent calls to actually do the work: run AFL, compile a harness, store a crash, read a coverage report, and so on.
The design rule I cared about most is a clean separation of responsibility: the LLM agent owns the decisions, and the MCP tools own the execution. The agent decides what to fuzz, what harness to write, and what coverage gap to chase next. The tools just expose primitives like run_afl_for or compile_harness. The agent never calls AFL or clang directly; it composes the pipeline out of these building blocks. All the state lives in a SQLite database (fuzz_context.db), so the stages never hand data to each other in memory, only through the database.
One small but important detail: each harness is built twice. AFL’s edge instrumentation is great for guiding the fuzzer but useless for human-readable coverage reports. So every harness becomes both a .afl binary (built with afl-clang-lto -fsanitize=address,undefined) and a .cov binary (built with clang -fprofile-instr-generate -fcoverage-mapping). The .afl binary does the fuzzing; the .cov binary replays AFL’s queue afterwards to produce real source-line and branch coverage.
The coverage-feedback loop
This is the heart of the whole pipeline, and it’s the part that most directly automates the manual workflow I described at the start.
If you have ever tried to improve fuzzing coverage by hand, you’ll know that it’s an iterative process that looks like this:
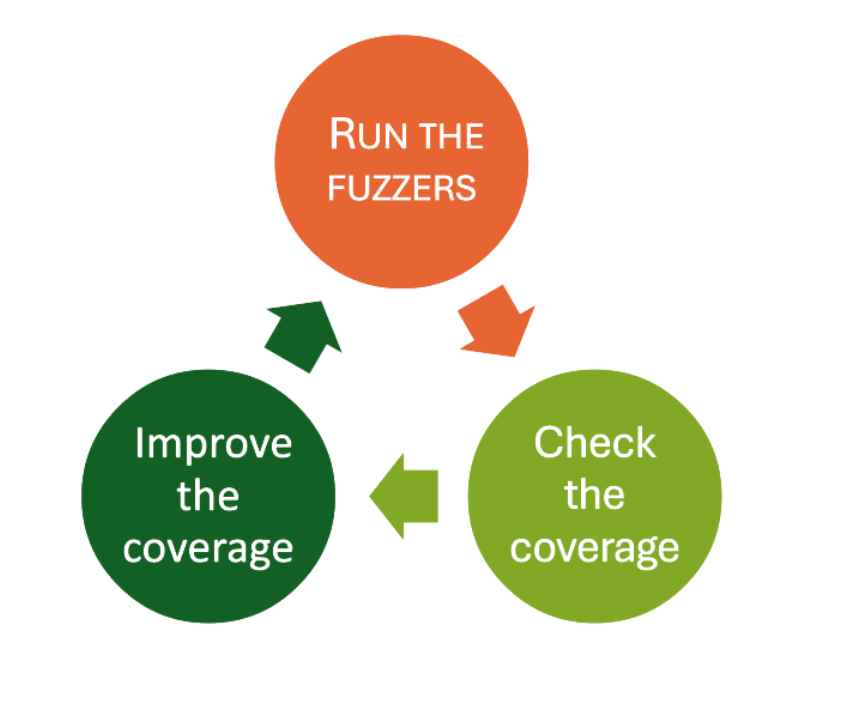
The “check the coverage” step used to be completed by me, manually reading an LCOV report looking for uncovered branches. The “improve the coverage” step was also completed by me, this time, writing a new harness or crafting a new input. The Fuzzing Taskflow hands both of those steps to the agent.
Each iteration, for each harness, the agent runs AFL for a time budget, replays the queue against the .cov binary to get a real coverage report, and then reads the list of uncovered branches. Based on what it finds, it picks one of a handful of actions:
- Add a new seed crafted to reach an uncovered branch
- Edit the harness source to call an additional API
- Auto-enrich the AFL dictionary with the magic constants a guard is comparing against
- Simply skip the gap if it’s a cold error path or vendor code that isn’t worth chasing
The time budgets double every iteration:
30s → 60s → 120s → 240s → 480s → 960s (≈ 32 min/target)
The idea is to spend cheap, short rounds early (when there’s lots of low-hanging coverage to grab) and longer rounds later (when the fuzzer needs more time to break through a hard guard).
And just like in my manual workflow, I need an answer to the question: when do we stop? Here, the loop uses plateau detection: once two consecutive iterations each gain less than a configurable threshold (1% absolute line coverage by default), the loop decides it has hit diminishing returns and moves on. This keeps the agent from burning hours of compute squeezing out the last fraction of a percent.
Structure-aware fuzzing
AFL’s default byte-level mutators (bit flips, arithmetic, block splicing) do a great job on binary formats but struggle with structured, text-based inputs. The classic solution is to hand-write custom mutators for each format, which is tedious work. This time I want the pipeline to do that work for me, so it ships four complementary mechanisms for producing structure-aware inputs.
1. Per-format dictionaries and custom mutators. For targets whose input format is recognized (JSON, XML, regex, PNG, length-prefixed binary TLV), the taskflow ships pre-built AFL dictionaries and LLVMFuzzerCustomMutator C files. The JSON mutator does token splicing and balanced-bracket duplication; the XML one knows about tags, entities, and billion-laughs tokens; the regex one carries real ReDoS patterns. Each mutator delegates half of its mutations back to AFL’s default byte mutator, so we keep the engine’s randomization instead of fighting it.
2. A source level dictionary. For formats the pipeline doesn’t recognize, it generates a custom mutator on the fly by scanning the target’s own .c/.h files. It extracts string literals and 32-bit numeric constants (from #define, case, and enum), filters out the noise, and uses them as splice tokens. The intuition is simple: the most interesting magic values that a parser checks for are usually written down somewhere in its own source.
3. A dynamically generated AFL dictionary with coverage-driven enrichment. The same source-token set is also emitted as an AFL classic dictionary before iteration 1 (numeric constants in both endiannesses, so the fuzzer can satisfy a memcmp against a 4-byte magic regardless of host byte order). Then, after every coverage step, the pipeline looks at the guards near the uncovered lines (strncmp, memcmp, case 0xN, == ‘X’) and appends any new tokens it finds. The dictionary literally grows toward the code the fuzzer can’t yet reach.
4. A corpus-splice operator. The smart mutator can also load files from a corpus directory and splice random sub-regions of them into the input, a recombination-style operator that AFL’s stock havoc doesn’t do well.
Evolving corpus
One of the things that quietly kills fuzzing efficiency is throwing away progress. If every run starts from the original seeds, you re-pay the cost of rediscovering the same paths over and over.
To avoid that, every harness gets a stable corpus directory that survives across iterations and across entire campaigns:
<workspace>/corpus/harness_<id>/At the end of each iteration, AFL’s queue is merged into this directory and run through afl-cmin to keep its size bounded. The effect is that yesterday’s interesting inputs carry into today’s run, and the inputs you found in last week’s campaign carry into this one. If you stop and restart a campaign, you lose nothing.
Triage and vulnerability reports
Finding a crash is only half the job. As anyone who has done root-cause analysis knows, triaging is often the most tedious part of the whole process. This is the other place where the agent shines.
After the fuzzing loop finishes, three stages run automatically. First, every crash is minimized with afl-tmin, replayed under ASan to capture a stack trace, and deduplicated by a stack-top hash (the top normalized frames, with templates, inline namespaces, and LTO suffixes stripped so semantically identical crashes collapse together). Second, previously known crashes are replayed against the current binary to see whether an upstream fix has resolved them. Third, the agent reads the harness source and the crashing function, walks the call chain back from the public API, and writes a per-crash markdown report.
Each report assigns one of the following verdicts:
- vulnerability
- library_hardening
- harness_bug
- OOM
- timeout
- assertion_failure
- duplicate
The distinction between a real vulnerability (reachable and exploitable through a public API) and a mere harness_bug (the bug is in our own harness, not the library) is exactly the kind of judgment call that used to require me to sit down and trace the code by hand. Every report includes a root-cause analysis with file:line references, a reachability argument, an exploitability assessment, a suggested fix as a unified diff and a regression-test sketch.
Just as clarification: the suggested patches are marked “review required” for a reason. The agent’s analysis is limited by the model’s understanding of the target code, and it does get things wrong. Treat the verdicts as a very well-prepared starting point for a human, not as final result.
Running an autonomous campaign and not being able to see what it’s doing is uncomfortable, so the pipeline publishes everything to a live HTML dashboard. It auto-starts in the background as soon as you launch a campaign, on port 8765. In a Codespace that port is auto-forwarded, so you can open it in any browser and watch the campaign progress in real time on the dashboard.
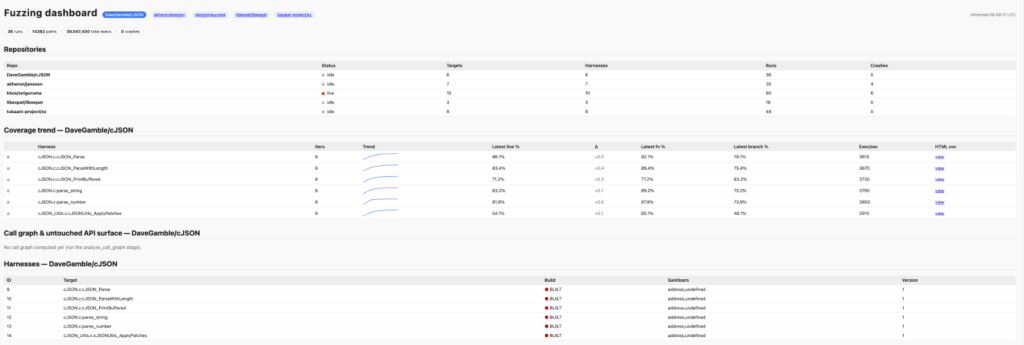
The page shows amongst others:
- a per-harness “running” pulse
- a coverage-trend table with inline sparklines
- a crash heatmap
- an iteration timeline
I started this project motivated by the limitations that any security researcher knows well: fuzzing works, but it doesn’t scale without human attention, and that human attention is the bottleneck. The Fuzzing Taskflow is my attempt to push that bottleneck back by handing the repetitive parts (writing harnesses, reading coverage, chasing gaps, triaging crashes) to an LLM agent, while keeping a clean separation between the agent’s judgment and the tools that do the real work.
If you’re the maintainer of C/C++ project, then please give it a try. If your project has never been fuzzed before, then this tool will help you to get started quickly. Or if your project has been fuzzed before, then this tool might help to find new bugs by increasing your fuzzing coverage.
The source code is open source, so please create an issue if you encounter any bugs. Contributions are also welcome!
Written by
文章来源: https://github.blog/security/application-security/ai-powered-fuzzing-with-the-github-security-lab-taskflow-agent/
如有侵权请联系:admin#unsafe.sh
如有侵权请联系:admin#unsafe.sh