What 270K monthly users taught me about admission control in browser-native media processingDisclos 2026-8-25 14:0:4 Author: hackernoon.com(查看原文) 阅读量:12 收藏
What 270K monthly users taught me about admission control in browser-native media processing
Disclosure: I build Video to Frames, the production application discussed in this article. This is an engineering postmortem based on aggregate technical metrics; it is not sponsored content.
A browser application told me that 92% of its video-processing jobs were successful. That number was technically correct — and operationally misleading. The metric only counted videos that entered the processing engine. If the application rejected a video because it exceeded a file-size or frame-count limit, that user disappeared from the denominator. By making the product more restrictive, I could make the success rate look better.
The solution was not another decoder optimization. It was to redefine success around the user's attempt, treat admission control as part of the processing system, and assign different limits to different device capabilities.
The resulting high-capability-device experiment increased task completion by as much as 6 percentage points. At one rollout stage, the upload block rate fell from 10.01% to 5.30%, while engine reliability remained approximately 96%.
This article explains the metric bug, the browser architecture behind it, and how to experiment with client-side capacity without turning low-end devices into crash reports.
In a Client-Side App, the User's Device Is Your Infrastructure
Server-side applications have relatively controlled infrastructure. You choose the instance type, memory allocation, deployment region, runtime, and autoscaling policy. A request from an old Android phone and a request from a recent desktop eventually arrive at infrastructure you control. Client-side computing reverses that relationship.
The user's device becomes the worker: - Its memory is your memory limit. - Its CPU is your processing capacity. - Its browser determines which codecs are available. - Its hardware decoder determines whether a job takes seconds or minutes. - Its storage quota determines how much intermediate output can be retained. - Its thermal state can change performance during the same task.
In aggregate measurements from a browser-native video tool, I observed WebCodecs decode throughput ranging from roughly 60 frames per second on weaker devices to around 960 frames per second on stronger ones. A single global frame limit was therefore not really a safety policy. It was a lowest-common-denominator policy. It simultaneously underestimated strong devices and overestimated weak ones.
The Metric That Rewarded Rejecting Users
The original metric was conventional: ```text processing success rate = successful jobs/jobs that entered processing
After several rounds of engine work, it improved from approximately 63% to 92%.
That improvement was useful. It showed that the processing pipeline had become more reliable.
But it did not answer the more important question:
Of all users who selected a valid video, how many actually received their frames?
Suppose 100 users select valid files:
- 70 are admitted into processing.
- 64 complete successfully.
- 6 fail during processing.
- 30 are blocked before processing.
The engine success rate is:
64 / 70 = 91.4%
The user-level task completion rate is:
64 / 100 = 64%
Both numbers are accurate. They measure different systems.
The first measures the processing engine.
The second measures the product.
Worse, if I tightened the admission rules and only allowed the 50 easiest videos through, the engine success rate might rise to 98%, even though fewer users completed their task.
A success metric that excludes rejected work creates the wrong incentive.
A Better Outcome Model
I changed the measurement boundary from "processing started" to "a valid video was selected."
Every valid upload attempt is designed to end in one of four outcome categories:
r_block + r_fail + r_complete + r_abandon = 1
Where:
r_complete = successful tasks / valid video uploads
r_block = rule-blocked uploads / valid video uploads
r_fail = processing failures / valid video uploads
r_abandon = cancelled or abandoned tasks / valid video uploads
The north-star metric became r_complete.
The other rates became diagnostic metrics.
This produces two legitimate ways to improve the product:
- Reduce
r_failby making the engine more reliable. - Reduce
r_blockby safely admitting more work.
It also creates a simple test for capacity changes:
decrease in r_block > increase in r_fail
If this condition holds, task completion rises.
If the block rate falls by 4 percentage points but the processing failure rate rises by 7 points, the product did not improve. It merely moved the failure from before processing to after the user had waited.
Instrumentation Has to Begin Before Processing
The new metric required events at the admission boundary, not only inside the engine.
A simplified event model looks like this:
type UploadOutcome =
| 'blocked'
| 'completed'
| 'failed'
| 'cancelled'
| 'abandoned';
interface UploadTelemetry {
uploadId: string;

deviceScore: number;
deviceTier: 'high' | 'mid' | 'low';
isMobile: boolean;
hasWebCodecs: boolean;

containerFamily: string;
fileSizeBucket: string;
estimatedFramesBucket: string;

activeFrameLimit: number;
experimentVariant: string;

outcome: UploadOutcome;
processingPath?: 'webcodecs_opfs' | 'ffmpeg_wasm';
durationBucket?: string;
errorType?: string;
}
The important property is not the exact schema. It is that policy decisions and terminal outcomes share the same upload identifier.
Without that link, I could see that blocking happened and that failures happened, but I could not reliably ask:
- Which device tier was blocked?
- Which limit was active at the time?
- What would have happened if this upload had been admitted?
- Did treatment increase failures specifically in the newly admitted range?
- Was an apparent latency regression caused by slower code or simply larger tasks?
I also monitor unmatched processing sessions. Instrumentation is designed to produce one terminal outcome per valid upload, but browser tabs can disappear, refresh, crash, or lose connectivity before the final event is recorded. Treating unmatched sessions as a data-quality guardrail prevents a clean-looking dashboard from hiding missing terminal events.
No source video, frame content, or filename is needed for this analysis. Coarse input characteristics and aggregate outcomes are sufficient.
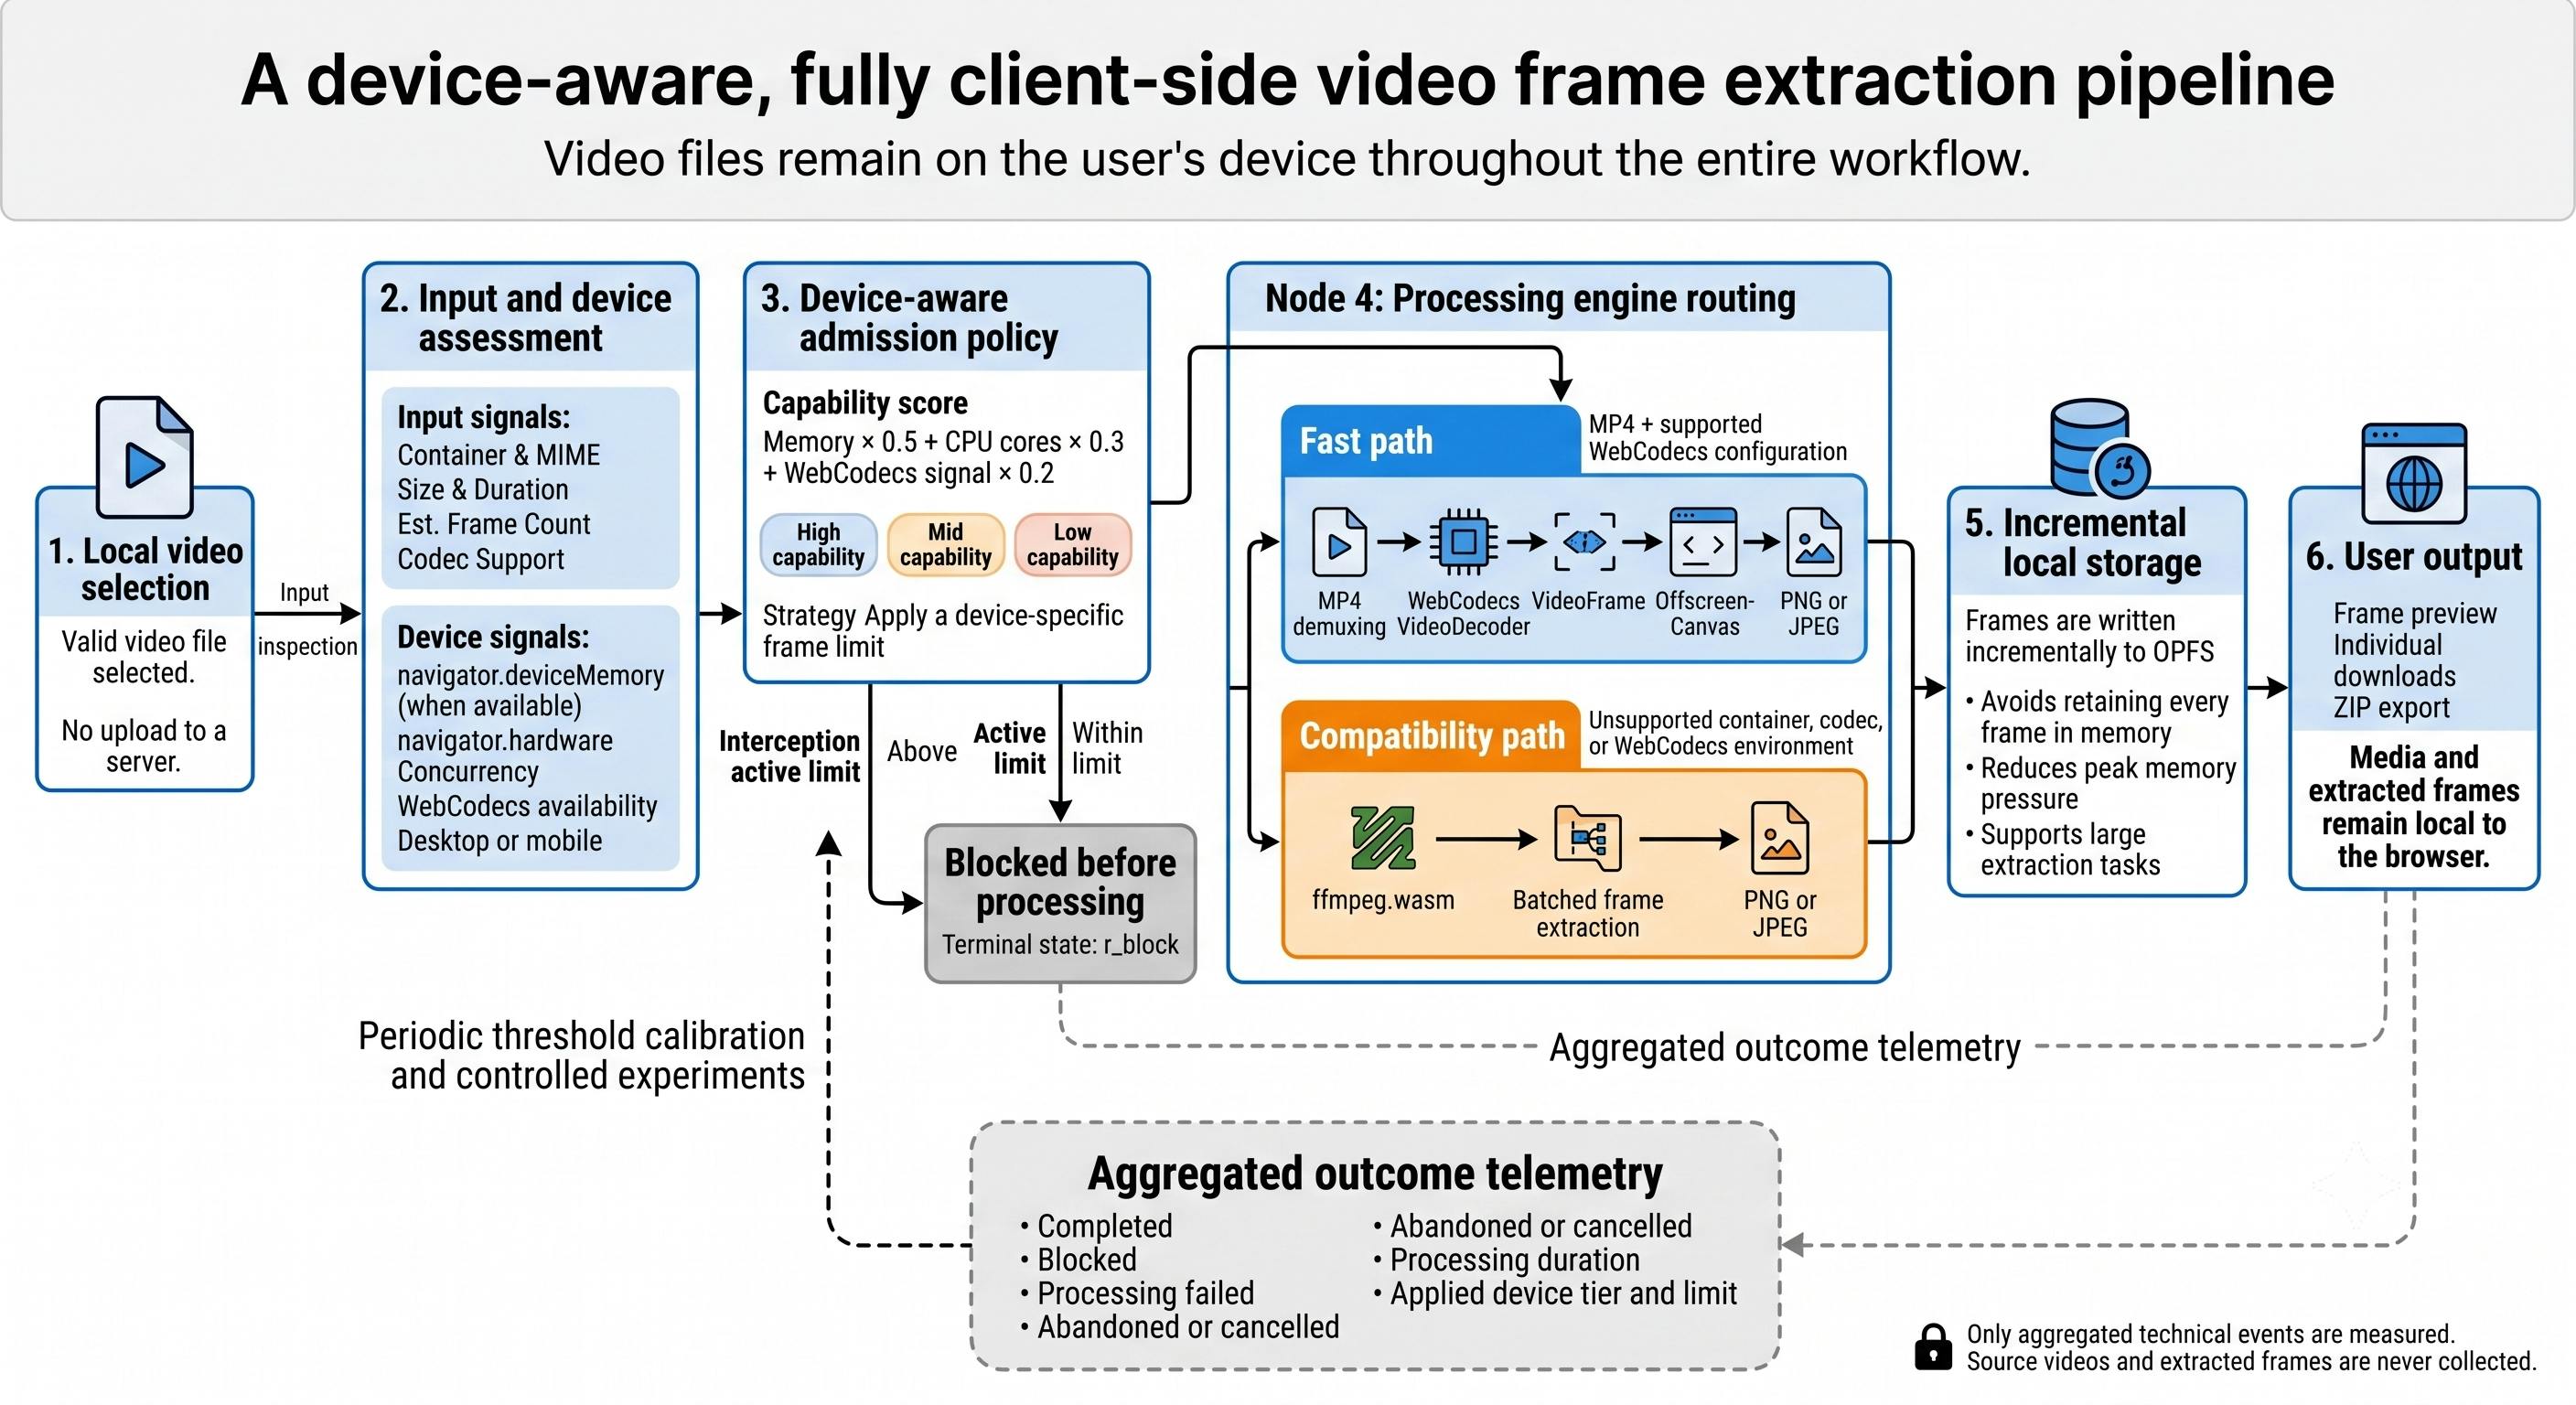
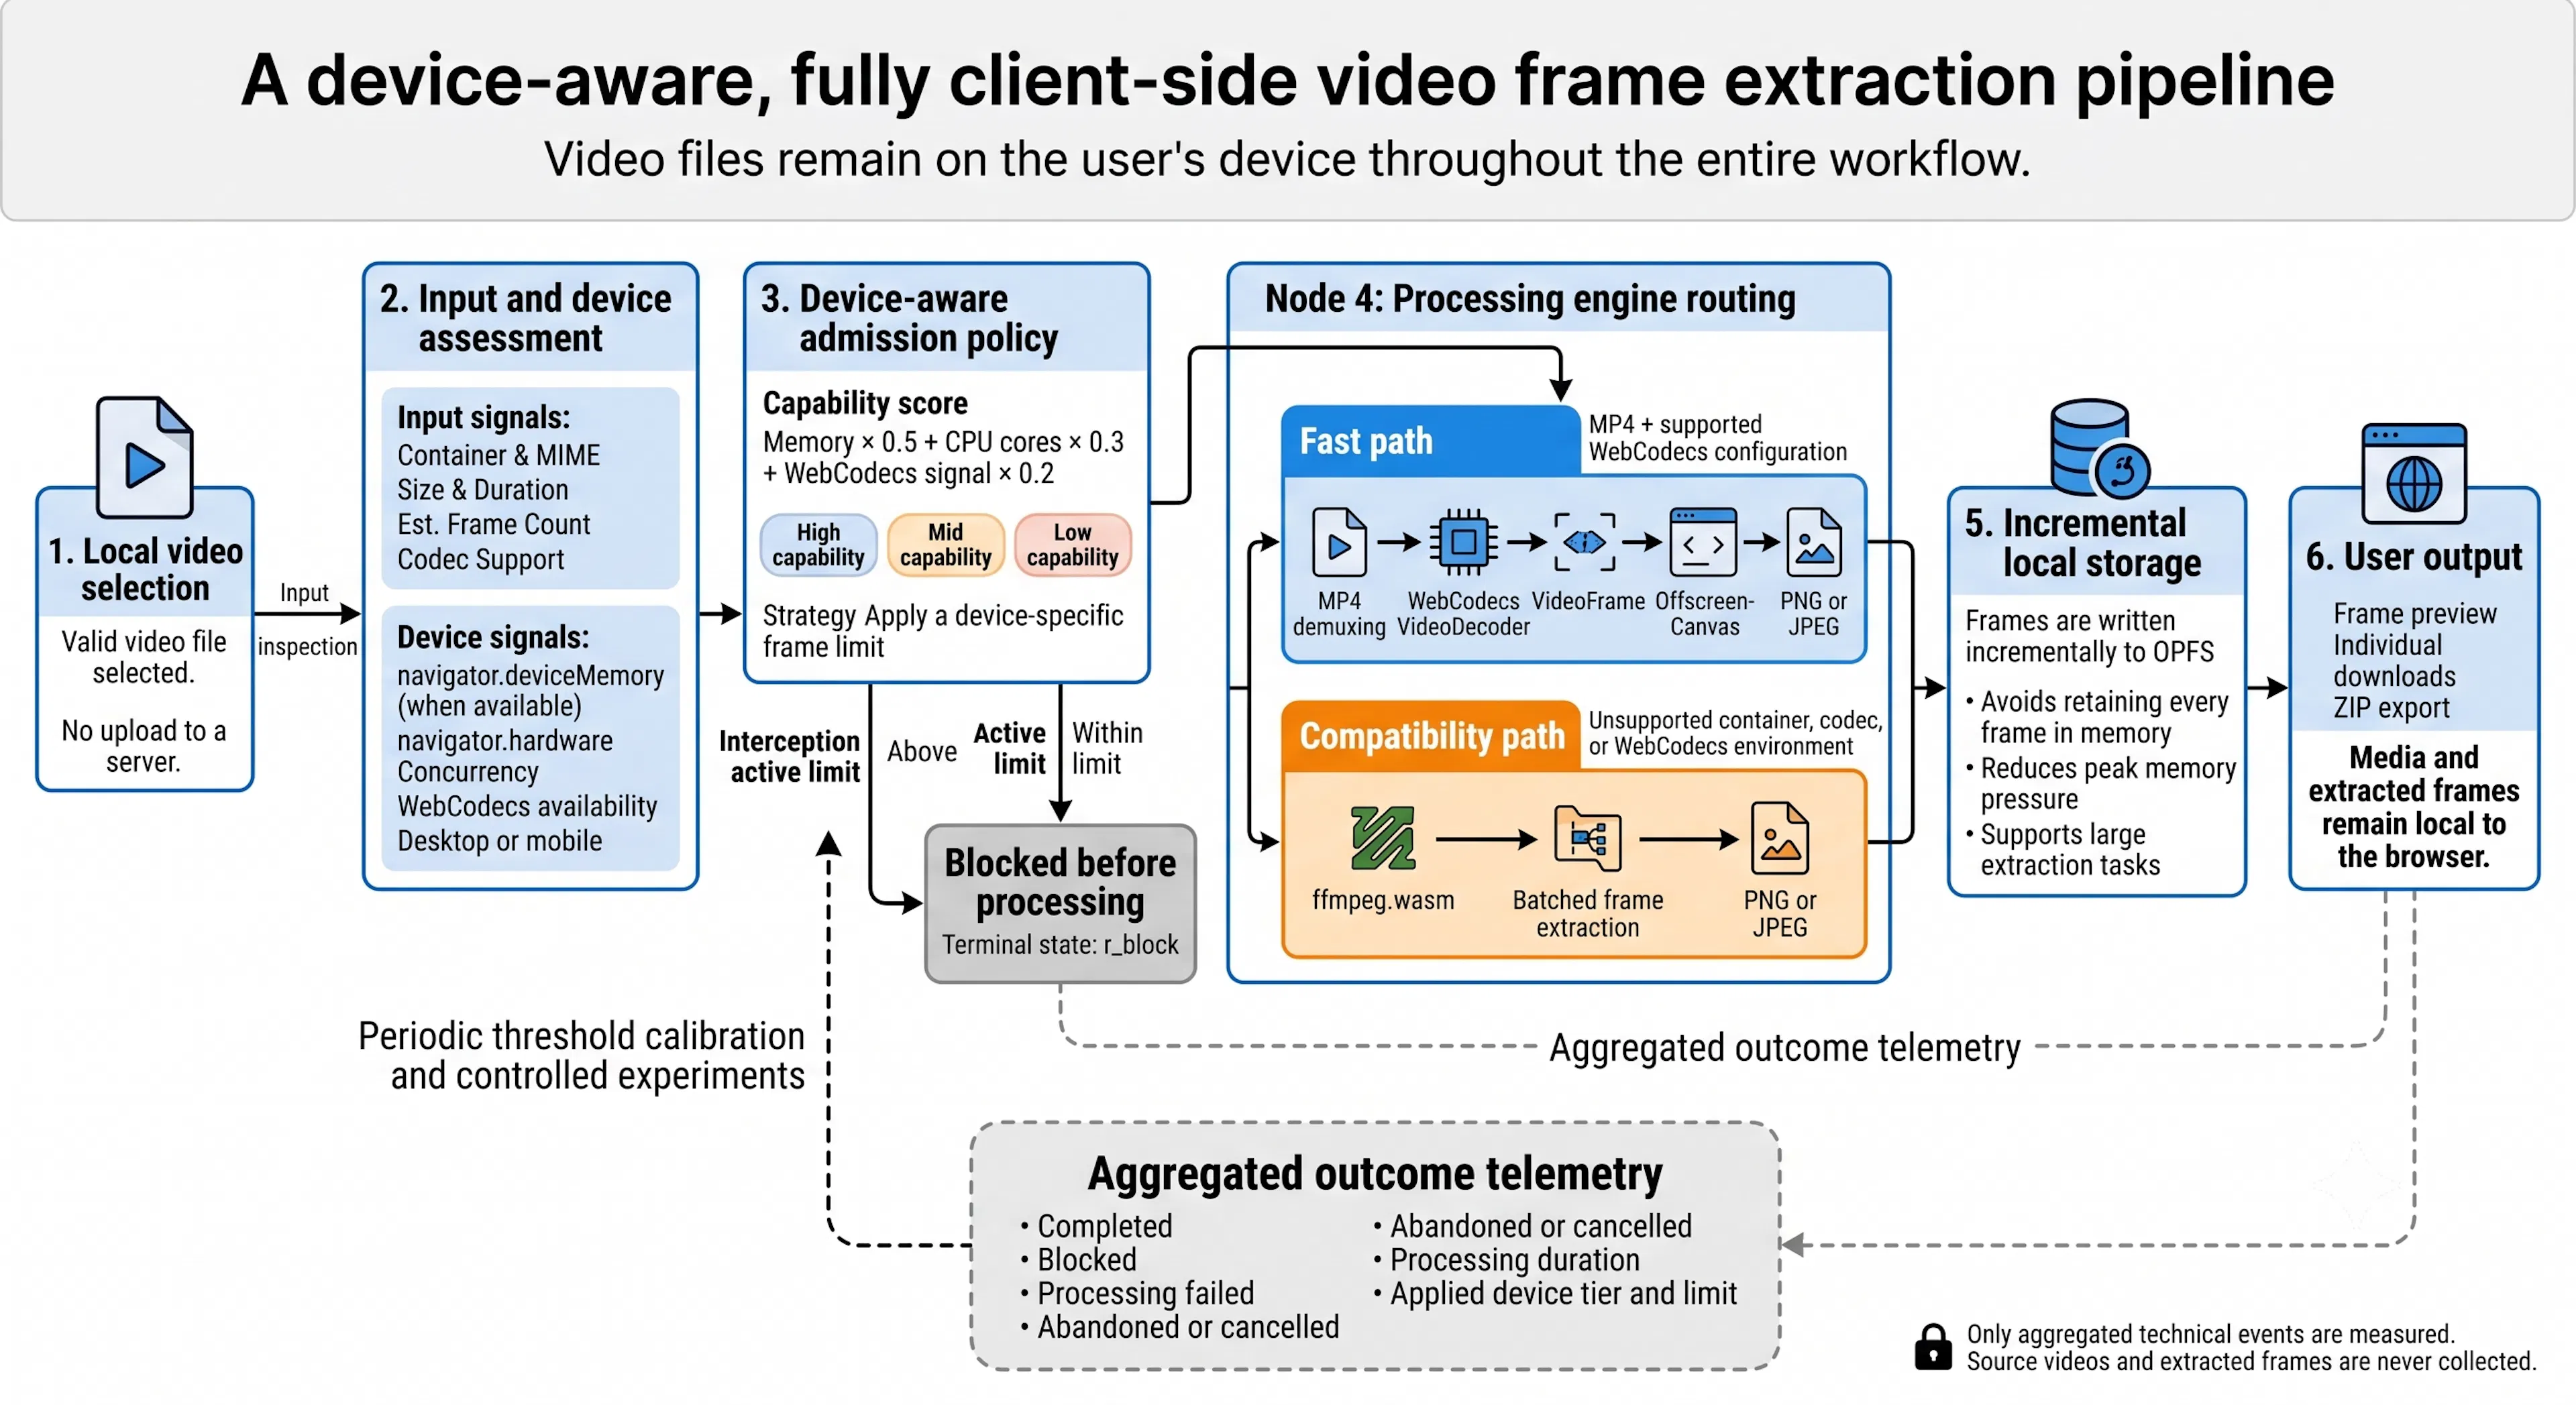
The Processing Pipeline: WebCodecs First, WASM When Necessary
The application uses two processing paths.
For compatible MP4 inputs, it uses the browser's WebCodecs API:
MP4 demuxing
→ EncodedVideoChunk
→ VideoDecoder
→ VideoFrame
→ OffscreenCanvas
→ PNG or JPEG
Before committing to that path, it checks whether the actual decoder configuration is supported:
const support = await VideoDecoder.isConfigSupported(decoderConfig);

if (!support.supported) {

}
Checking for the existence of VideoDecoder is not enough. A browser can implement WebCodecs without supporting the codec, profile, level, or resolution of a particular input.
Unsupported containers and decoder configurations use an ffmpeg WebAssembly compatibility path.
This is slower and more memory-sensitive, but it gives the product broader format coverage.
The routing decision is therefore based on both environment and input:
function chooseProcessingPath(input: VideoInput, device: DeviceInfo) {

if (
input.container === 'mp4' &&
device.hasWebCodecs &&
input.decoderConfigSupported
) {
return 'webcodecs_opfs';
}
return 'ffmpeg_wasm';
}
The goal is not to eliminate WASM. It is to avoid paying its memory and CPU costs when the browser already exposes hardware-accelerated media primitives.
OPFS Changed the Memory Shape of the Job
Extracting hundreds or thousands of frames creates another problem: output accumulation.
Keeping every encoded image in an array of blobs makes memory usage grow with the number of frames. Even if decoding is efficient, output retention can eventually terminate the tab.
Instead, frames are written incrementally to the Origin Private File System:
async function saveFrame(

root: FileSystemDirectoryHandle,
blob: Blob,
index: number
) {
const filename = `frame_${String(index).padStart(4, '0')}.jpg`;
const fileHandle = await root.getFileHandle(filename, {
create: true
});
const writable = await fileHandle.createWritable();
try {
await writable.write(blob);
await writable.close();
} catch (error) {
await writable.abort?.();
throw error;
}
return filename;
}
The UI retains metadata and a limited preview set. The full output lives in browser-managed local storage until the user downloads or clears it.
This does not make memory usage free. Decoders, canvases, WASM heaps, and concurrent writes still consume memory.
But it changes output memory from approximately:
O(total extracted frames)
toward:
O(active decode and encode window)
That is a much safer shape for large client-side jobs.
Scoring Devices Without Pretending the Score Is Truth
A browser does not expose a trustworthy "this device can process exactly 1,437 frames" API.
The available signals are coarse:
navigator.deviceMemory, where supported.navigator.hardwareConcurrency.- WebCodecs availability and configuration support.
- Mobile or desktop classification.
- Observed results from previous aggregate cohorts.
The initial capability score was intentionally simple:
function getDeviceScore() {

const memory = navigator.deviceMemory || 4;
const cores = navigator.hardwareConcurrency || 4;
const webCodecsSignal = 'VideoDecoder' in window ? 2 : 0;
return roundToOneDecimal(
memory * 0.5 +
cores * 0.3 +
webCodecsSignal * 0.2
);
}
function getDeviceTier(score: number) {
if (score >= 7) return 'high';
if (score >= 4) return 'mid';
return 'low';
}
This is not machine learning, and I do not describe it as a prediction model.
It is an admission-control heuristic.
Memory receives the largest weight because memory exhaustion is a hard failure for the WASM path. CPU count strongly influences duration but is less directly connected to whether a task completes. WebCodecs changes the processing path entirely.
Missing information uses conservative defaults.
The score does not grant unlimited capacity. Every tier is still bounded by a hard ceiling.
The production rule is closer to:
function getActiveLimit(context: ProcessingContext) {
if (

context.deviceTier === 'high' &&
context.isDesktop &&
context.isMp4 &&
context.hasSupportedWebCodecs
) {
return context.experimentLimit;
}
return context.defaultLimit;
}
A key lesson was to avoid turning the score into a false precision machine.
A score of 6.8 is not meaningfully more certain than 6.7. The useful output is a small number of operational tiers that can be tested independently.
Experimenting Without User Accounts
The next challenge was assignment.
The product does not require an account, and the experiment did not need one. Each upload received an identifier, and eligible uploads were assigned through a deterministic hash of the experiment name and upload ID:
function getStableHashPercent(value: string) {

let hash = 0;
for (let i = 0; i < value.length; i++) {
hash = ((hash << 5) - hash + value.charCodeAt(i)) | 0;
}
return Math.abs(hash) % 100;
}
function getVariant(
experimentName: string,
uploadId: string,
rolloutPercent: number
) {
const bucket = getStableHashPercent(
`${experimentName}:${uploadId}`
);
return bucket < rolloutPercent
? 'treatment'
: 'control';
}
This is not a cryptographic hash, nor does it need to be. It only needs to provide deterministic, approximately uniform bucketing for the experiment population.
Eligibility is evaluated before assignment.
For the first capacity experiment, the eligible population was deliberately narrow:
- Desktop devices.
- High capability tier.
- MP4 input.
- WebCodecs available and usable.
- No change to the compatibility path.
The control retained an 800-frame limit. Treatment received a 1,600-frame limit.
The experiment progressed through 25%, 50%, 75%, and finally full rollout for the eligible population.
Guardrails Matter More Than the Uplift
The obvious metric was task completion.
But a capacity experiment can improve completion while damaging the experience in less visible ways. I therefore used veto-style guardrails:
- Processing engine success must stay above the safety threshold.
- Engine success must not materially underperform concurrent control.
- P90 processing duration must not regress for comparable workloads.
- Long-tail tasks must not increase abnormally.
- Cancellation and abandonment must not spike.
- Missing terminal outcomes must not increase.
"Comparable workloads" is important.
Treatment admits jobs with 801–1,600 frames. Control cannot admit those jobs. Comparing raw treatment latency with raw control latency would guarantee that treatment looks slower because it contains structurally larger work.
For latency, I compared only the shared 0–800-frame range:
control tasks: 0–800 frames
treatment tasks: 0–800 frames
The newly admitted range was evaluated separately for completion and abandonment.
This avoids a common experiment-analysis mistake: attributing a population shift to a code regression.
What Happened
The task-completion uplift was positive at every measured rollout stage:
25% treatment rollout: +6.0 percentage points
50% treatment rollout: +5.9 percentage points
75% treatment rollout: +3.6 percentage points
At the 75% stage:
control block rate: 10.01%
treatment block rate: 5.30%
The block rate was approximately 47% lower.
Blocks in the newly opened 801–1,600-frame range disappeared for treatment, which is the expected mechanism if the threshold change is working correctly.
Meanwhile:
- Engine success remained approximately 96%.
- The shared 0–800-frame workload showed no long-tail latency regression.
- The experiment eventually reached the full eligible population.
This is not evidence that every device should receive a 1,600-frame limit.
It is evidence that this specific eligible cohort had unused capacity and that releasing it improved the user-level outcome without crossing the safety guardrails.
That distinction matters.
Five Mistakes I Would Avoid Next Time
1. Optimizing an engine metric as if it were a product metric
Engine success is useful for diagnosing the decoder.
It should not be the only north star when admission rules decide which jobs the engine gets to see.
Always place the main denominator at the earliest meaningful expression of user intent.
2. Treating a rejected task as if nothing happened
A preflight rejection avoids a crash, but it is still an unsuccessful user task.
Blocks belong in the product outcome model even when they do not belong in the engine reliability metric.
3. Increasing a global limit
A global increase mixes together devices, containers, codecs, and processing paths with very different risk profiles.
Start with the cohort whose behavior is easiest to predict.
4. Comparing unlike latency populations
If treatment admits larger work, its raw duration distribution will change even when the implementation does not.
Compare shared workloads for regression analysis and evaluate newly admitted workloads separately.
5. Reaching for machine learning too early
A few coarse tiers, calibrated from real outcomes, were easier to understand and safer to roll back than an opaque prediction model.
Use a model when the data and decision complexity justify it — not because "device scoring" sounds like a machine-learning problem.
A Reusable Admission-Control Checklist
The same pattern applies beyond video frame extraction.
Browser-side image upscaling, speech recognition, OCR, audio separation, local LLM inference, and document processing all face heterogeneous client capacity.
A practical rollout checklist is:
Measurement
- Define the attempt before admission.
- Include blocks in the product denominator.
- Preserve a separate engine-reliability metric.
- Record policy version and active limit.
- Monitor missing terminal outcomes.
Capability segmentation
- Use coarse, privacy-preserving device signals.
- Include the selected processing path.
- Prefer a few explainable tiers.
- Use conservative defaults for missing APIs.
- Keep hard upper bounds.
Experimentation
- Define eligibility before assignment.
- Use stable bucketing.
- Compare concurrent control and treatment.
- Change one capacity variable at a time.
- Progressively increase exposure.
Guardrails
- Require minimum engine reliability.
- Compare latency on shared workload ranges.
- Monitor long-tail duration.
- Monitor cancellation and abandonment.
- Make rollback cheap.
The Broader Lesson
Moving computation into the browser removes server processing cost and can improve privacy, but it does not remove infrastructure management.
It relocates infrastructure management into product logic.
The application now has to answer questions that would normally belong to a scheduler:
- Is this worker capable of running the job?
- Which execution path should it use?
- How much work should be admitted?
- How should output spill to storage?
- When should the task be rejected?
- How do we expand capacity without lowering reliability?
The biggest improvement did not come from pretending every browser was equally powerful.
It came from measuring the work we refused to attempt, treating those refusals as real outcomes, and releasing capacity one device cohort at a time.
If your client-side success rate only begins after admission, inspect the denominator.
It may be telling you how reliable your engine is.
It is not necessarily telling you how many users succeeded.
如有侵权请联系:admin#unsafe.sh